Note to the reader
A link to an updated version (or even a newer edition) of this paper may be available on the WWP bibliography page.
Introduction & argument
This paper explores the impacts of complexity on the
creation and use of XML documents, with a focus on human
experiences of complexity. In order to discuss this topic in
detail, it would be helpful to have a method of measuring
complexity, which we assert does not (yet?) exist. Furthermore,
complexity in the markup itself does not always correlate with
complexity in writing, proofing, reading, and processing the
XML — what one might call
operational complexity. Thus, measurements of
complexity that focus purely on metrics — counting
elements or attributes, comparing the density of markup relative
to textual contents, measuring the diversity of element
types — provide only a partial view of complexity
from the perspective of the projects and individuals using the
XML. For example, the Text Encoding Initiative provides an
<lb> element for marking the beginning of new
lines. Using <lb>s to encode each new line from a
printed source text might expand the number of elements in a
document by the tens of thousands, but this also makes the
document dramatically easier to proofread, navigate, and compare
with the source file. In this paper, we discuss some features
of complexity as it impacts the sharing and reuse of XML files,
the longevity and sustainability of XML projects, the consistency
and quality of encoded texts, and the planning and implementation
of encoding work.
While the authors must confess an interest in measuring complexity for its own sake, increased precision around understanding and weighing the sources of complexity faced by XML projects is also essential for anticipating and mitigating these. As we discuss below, it is often the case that projects can choose to relocate complexity from one process or stage of project development to another — for example, making the encoding more complex in order to simplify processing, or the reverse. Approaching such decisions strategically requires that projects are able to: 1) recognize the full spectrum of locations in which complexity will manifest, 2) measure (or, at least, evaluate) those sources to determine where relocating complexity will most impact the project’s efficiency, 3) recognize both where complexity is unavoidable and where any processes or decisions will lead to unnecessary complexity, and 4) iteratively revisit the project’s processes to determine where these may need to be adjusted. By offering a framework for identifying sources of complexity in XML project work and suggesting additions to syntax-based complexity metrics, we hope to offer some considerations that will be useful to XML project planning and discussions around understanding complexity in work with XML.
As C. M. Sperberg-McQueen argues in his closing keynote from Balisage 2021, complexity is an issue that most XML projects need to address. He writes:
There is more than one subjective notion of simplicity and more than one subjective notion of complexity. But however we perceive it and however the users of the systems we build perceive it, we need to deal with complexity. We need to control it. We need to find ways to minimize it.
This paper is far from the first to consider the ways that
complexity in XML documents and schemas can be measured. Numerous
studies, especially in the computer sciences, have offered metrics
for evaluating XML complexity. For instance, Ruellan (2012) offers a comprehensive formal study of
the quantity of information contained in XML documents,
classifying XML complexity according to three metrics:
|
Size |
measured according to the size in bytes of the XML document’s serialization, |
|
Information density |
measured |
|
Structure regularity |
computed by taking |
In this paper, we will refer to such metrics as syntactic complexity. In no way do we wish to suggest that syntax is not useful for understanding the impacts of complexity on work with XML; indeed, we offer several of our own approaches for considering a variety of syntactic features. However, we wish to expand upon syntactic metrics to explore several other sites of complexity in XML workflows, including the semantics of the markup, the ways that markup is edited and processed, and the lifecycles of XML files. As might be clear already, this paper is situated within our own perspective of working with XML files primarily in the context of digital humanities projects. We think that this perspective is generalizable enough to be relevant in many — although, of course, not all — other applications. We offer this framework as a resource for continued work on studying the impacts of complexity on the use and sustainability of XML files.
We locate several sources of complexity within XML files and related systems. These include measures that evaluate XML files directly:
|
Syntactic complexity |
as measured by counting and comparing XML
structures. Syntactic complexity may be evaluated through
raw counts or through |
|
Semantic complexity |
as measured by considering how difficult XML files are to understand. That is, semantic complexity takes into account the idea that information formalized through markup might be complex or deeply theorized, even if it is expressed through a small number of elements or otherwise simple encoding. |
|
Processing complexity |
complexity that becomes evident when XML files are processed. There are often significant differences between how complex XML is to write and how complex XML is to process. |
|
Application complexity |
complexity that is not inherent to the markup itself but instead inheres in the human languages to which the markup is applied. This includes any features that demand extensive documentation to ensure that encoding remains consistent. |
|
Version complexity |
complexity within a document’s version history. Here, we examine complexity that is external to the XML but that can significantly impact the creation and use of encoded files, since even very simple files may have complex version histories. |
Schemas are another essential site for understanding XML complexity, as examined in several previous studies.[2] In considering schema complexity, we touch upon complexity within schemas themselves; we also look at several ways that schemas impact operational complexity. And finally, we locate complexity within the minds of the humans writing and interacting with XML files. Relevant to the human element of complexity in XML is what we call visual complexity, as experienced due to the appearance and layout of the markup. This is a space where humans and computers can diverge dramatically, since features such as indentation and whitespace can strongly impact complexity as perceived by humans.
Having outlined our approaches to understanding and
beginning to measure complexity, we offer two brief case studies
that reveal further complications that emerge through the
intersection of human activities and XML syntax. Here, we think
about ways that XML files can become complicated in terms of being
difficult to work with, with attention to
cases in which the things that make XML files challenging do not
correlate with the obvious forms of syntactic complexity. First,
we consider the usage of renditional defaults
(a
method for declaring the default value of an attribute) in TEI
files. From some perspectives, renditional defaults make TEI files
dramatically simpler, since they can reduce the number of
attributes specifying rendition for individual elements by the
tens of thousands. However, renditional defaults have a dramatic
impact on operational complexity, since they mean that encoders
must remember to override them where necessary, proofreaders need
to keep them in mind when reading encoded files, and systems for
processing the encoded files must take into account the fact that
rendition might be specified either locally or through defaults.
In the second case study, we consider the use of
sequence vs. containment
as information storage methods with respect to complexity,
positing that neither is particularly complicated on its own, but
that mixing the two may increase complexity without any obvious
benefit.
As the above indicates, this paper is deeply invested in
seeking to understand where complexity is located within XML
systems. This goal requires that we also address how complexity is
defined. As with its measurement, the definition of complexity has
received considerable scholarly attention; a thoughtful and
comprehensive overview of this work can be found in a recent
article by Beale et al. (2024)[3] This
article characterizes the definition of complexity as
contentious,
outlining sources and usages of several definitions
before offering the following definition, based on the authors’
analysis of usage insights: complex(ity) is when relationships
between elements are weaved together such that they are not fully
comprehended, leading to insufficient certainty between cause and
effect
(Beale et al. (2024)). The relationship between complicated
and complex
is
also an important definitional touchpoint: as Beale et
al. explain, the majority of dictionaries treat these terms as
synonyms, reflecting their most widespread usages, while
complexity theory treats the two terms as fundamentally
distinct. The precise difference between complex
and
complicated
is yet another space where there is considerable
divergence of thought — generally, systems or processes can be
described as complicated whenever they possess many components,
while there is a higher threshold for ascribing complexity,
usually involving unpredictability or a whole that cannot be
comprehended by examining its parts. A useful framework for
distinguishing these terms is published in the Complex Systems
Frameworks Collection by Diane Finegold (Finegold (2022)). Here, complicated systems are described as
predictable, controllable, and designable (that is, possible to
design around). Complex systems, by contrast, are inherently
unpredictable, heterogeneous, non-linear, and with interdependent
parts that impact each other’s behavior.
These distinctions can be useful in recognizing which
strategies will work best to manage any aspects of a project,
whether complex or complicated, that are not conveniently
simple. That said, in the authors’ experiences, complexity and
complication exist on a spectrum — for the individuals working on a
project, anything that becomes complicated enough will also be
complex to work with. Our primary goal for this paper is to locate
and assess the complexities that are experienced in XML project
work so that these can be better anticipated and managed. Thus,
for us, the most important meaning of complexity
would be the
one used and experienced by the individuals designing and
implementing XML projects. In the discussions that follow, we
treat complex systems as ones involving multiple component parts
that interact in ways that are difficult to predict. Since we
recognize that so much of the direct experience of complexity
is perspectival — given that one project’s
complicated
will be another project’s complex
— we use the term
complex
when it seems likely that the phenomenon under
discussion might be either complex or complicated, depending on the
circumstances. We reserve the term complicated
for situations in
which it seems clear that the features under discussion are only
complicated.
If we may be forgiven the potential tautology, this paper
argues that complexity is complicated — complexity itself comprises
many individual components. Here, we wish to expand our understanding of XML complexity
by thinking
seriously about how these various components interact. Despite our
interest in measurement, we are keenly aware that there is no
single yardstick
that can be used to quantify
complexity — as Sperberg-McQueen notes, complexity
is sometimes in the eye of the beholder
(Sperberg-McQueen (2021)). The weight and impacts of complexity will
depend on the XML, the person reading the XML, the data, the needs
of the project, and so on. Nevertheless, we think that having more
precise vocabularies for describing complexity — in
addition to more detailed understandings of how these different
forms of complexity interact with human work — can
only help. This paper is an effort to begin developing such
vocabularies and understandings.
Locations of complexity
In the XML instance
We find complexity (and simplicity, but that’s not
important right now) in various places in our lives in general,
and in our XML in particular. The first complexity
that most
of us think of is the syntactic complexity of the XML instance
itself. This notion is supported by the fact that all of the
prior work we discovered in a literature review of XML complexity
metrics was about the complexity of XML instances.
Syntactic
But we submit that, even when only talking about
syntactic complexity — which should be the
easiest to define — that we (at least we, the
authors, if not we, the entire XML community) do not know what
makes an XML instance more or less complex. Nonetheless, there
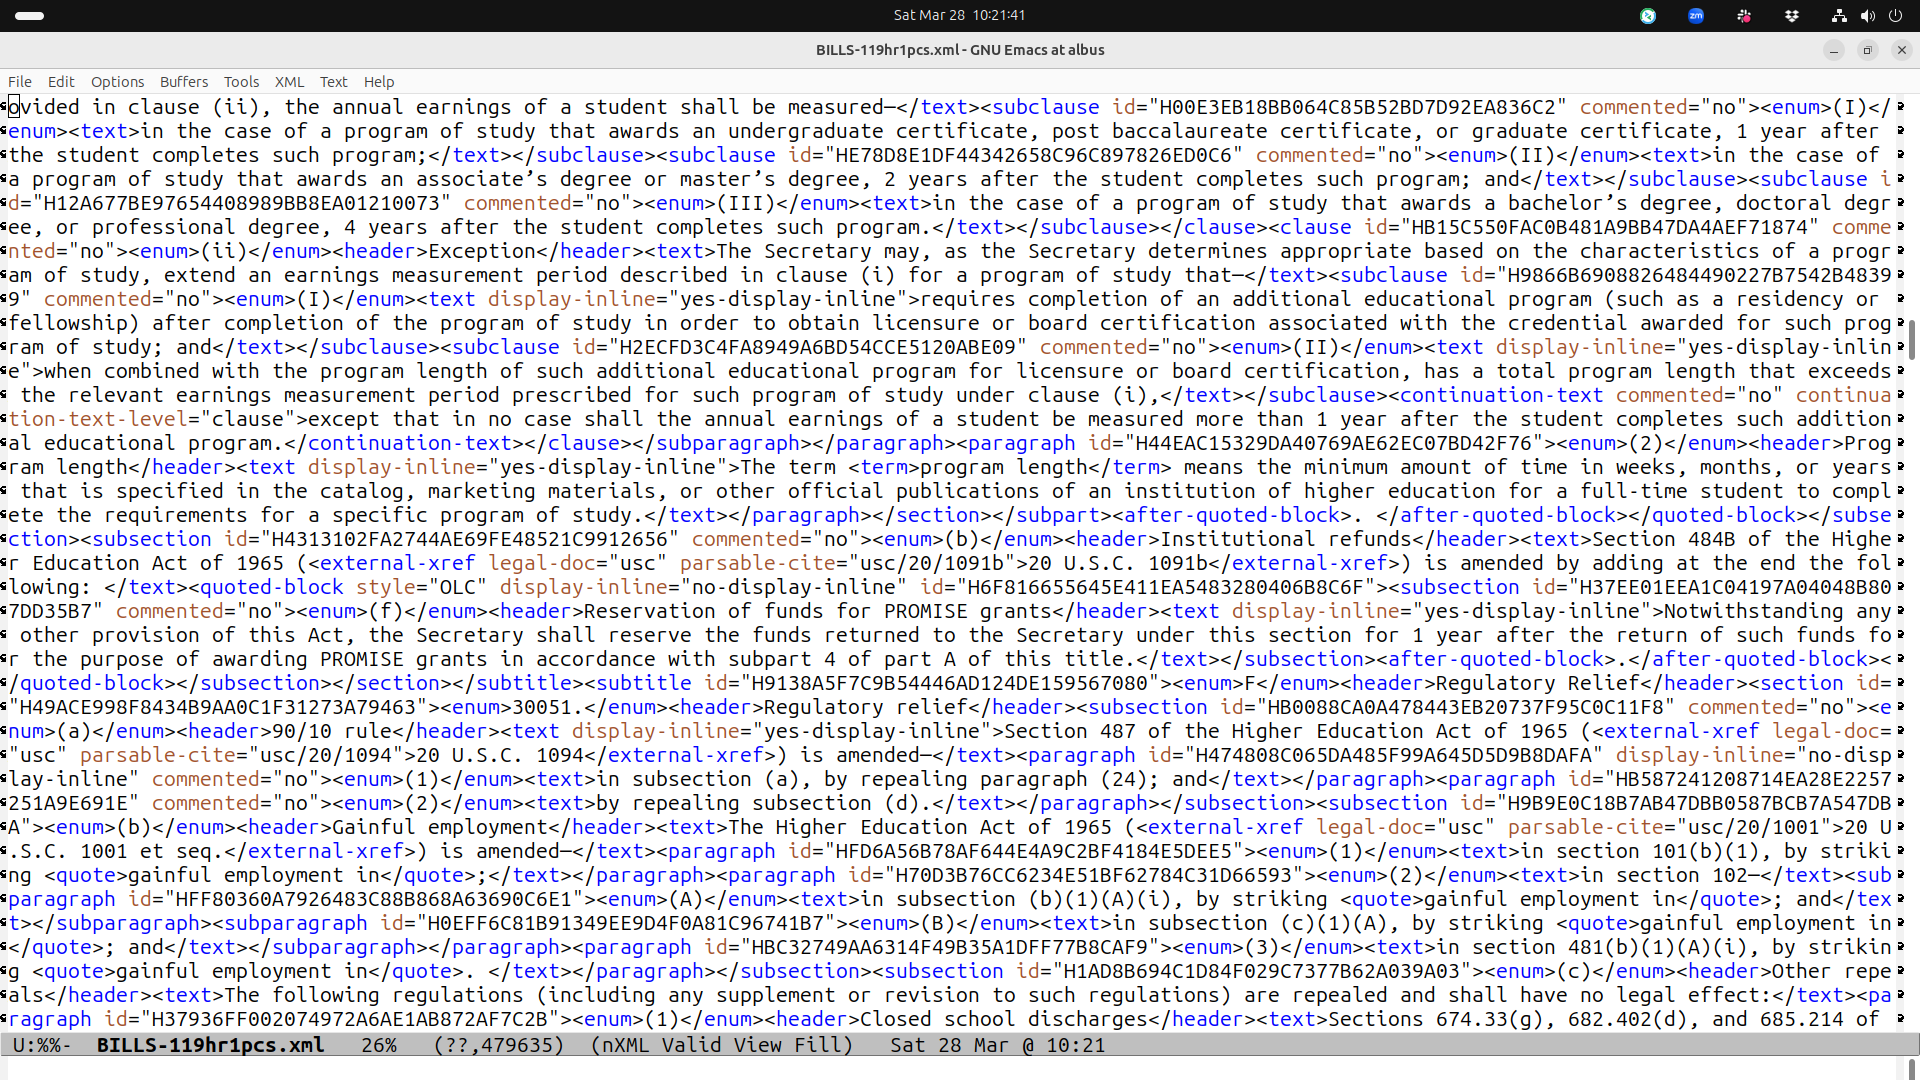
is no doubt that some documents are simple — see Figure 1.
Figure 1 Figure 2 A screenshot of ~6,120 characters worth of a single line
of XML (being edited in Emacs/nxml-mode on Ubuntu). It
contains 86 start-tags, 91 end-tags, and 50 attributes.[4]
<?xml version="1.0" encoding="UTF-8"?>
<msg>Hello World!</msg>
What is not clear is whether or not there is any
agreement as to which ones are complex, or what contributes to
complexity. But I know it when I see it
à la US Supreme Court
Justice Potter Stewart is not helpful with respect to
automated complexity detection, and is, to our knowledge,
completely untested. That is, no one has heretofore determined
that human perception of complexity matches any
particular metric of syntactic complexity, or even measured
inter-reviewer reliability of complexity detection in
XML.
Raw counts
Which begs the question: where might we look for metrics of syntactic complexity? Simple raw counts of syntactic structures may well be helpful, and are easy to produce. These raw counts could include (but are not remotely limited to) things like the following.
-
The ratio of element instances to the number of characters in the file
-
The ratio of element instances to the number of characters in text nodes
-
The ratio of element instances to the number of characters in text nodes other than whitespace-only text nodes
-
The ratio of element types to element instances (which, when subtracted from 1, is what Ruellan calls
structure regularity
) -
The ratio of attributes to element instances
-
The average length of attribute values
-
The average and maximum nesting depth of elements (the minimum is not interesting, it is ‘1’ :-)
Note that we are often using ratios and averages of simple raw counts, rather than the counts themselves, in an attempt to reflect our intuition that filesize itself does not contribute to complexity.
It is our instinct (with little to no evidence) that no single simple raw count, average, or ratio will effectively represent what humans perceive as syntactic complexity, but that some combination of a few of these may.
Fuzzy counts
By fuzzy counts
we do not mean counts that are not
precise, but rather precise counts of less rigid
phenomena. One big problem with the simple raw counts of
precise syntactical structures is that it does not take into
account even the syntactic complexity, let alone the
semantic complexity, of some element types vs others. For
starters, those syntactic structures that are used to handle
overlap problems (e.g., the TEI’s @next &
@prev attributes) lend significant complexity
to an instance, in that the data needs to be represented as
or at least considered as more than a single simple tree
structure.
Consider the TEI <g> element; its name
is short for gaiji
or 外字
, meaning (for our purposes) a
character that is not available in Unicode. It is in many
ways parallel to the <c> (for character)
element, but rather than contain as content a Unicode
character, it points via an attribute to an XML structure
that describes a character. This adds some semantic
complexity, sure; but just syntactically speaking, does a
<g> element count as zero characters of
content (because it is empty), one character (because it
represents one character), or however many characters are
used to describe the one character?
If you are counting words in a document, how do you
account for an acrostic? I.e., does Figure 4 have five
words or six?
Figure 4 Figure 5
    <surface>
      <line>Tyrannical</line>
      <line>Racist</line>
      <line>Unqualified</line>
      <line>Misogynistic</line>
      <line>Panderer</line>
    </surface>
<w>
elements, the encoder is asserting it has six words.
    <surface>
      <line><w><w xml:id="ac.01"               next="#ac.02">T</w>yrannical</w></line>
      <line><w><w xml:id="ac.02"prev="#ac.01"  next="#ac.03">R</w>acist</w></line>
      <line><w><w xml:id="ac.03"prev="#ac.02"  next="#ac.04">U</w>nqualified</w></line>
      <line><w><w xml:id="ac.04"prev="#ac.03"  next="#ac.05">M</w>isogynistic</w></line>
      <line><w><w xml:id="ac.05"prev="#ac.04"               >P</w>anderer</w></line>
    </surface>
Syntax ↛ Semantics
It is worth noting that syntactic complexity does not
necessarily imply semantic complexity. It is not unusual
when using a major tagset like JATS, DocBook, or TEI to find
cases for which it takes quite a bit of XML syntax to
represent relatively straightforward concepts. E.g., when
encoding the libretto
for The Phantom of the Opera in TEI, if one wishes to
indicate that the first letter sent by the Phantom is, in
fact, a letter, one may end up with the encoding in Figure 6.
Figure 6
  <sp who="#and">
    <speaker>ANDRE</speaker>
    <quote>
      <floatingText type="letter">
        <body>
          <salute>Dear Andre</salute>
          <l>what a charming gala!</l>
          <l>Christine enjoyed a great success!</l>
          <l>We were hardly bereft</l>
          <l>when Carlotta left</l>
          <l>otherwise</l>
          <l>the chorus was entrancing,</l>
          <l>but the dancing was a</l>
          <l>lamentable mess!</l>
        </body>
      </floatingText>
    </quote>
  </sp>
he (the character) is
reading a letter
requires encoding an extra three levels
deep.
As another example, the extract shown in Figure 7 is from a sample
article published on the NLM website.
Figure 7
  <p>We report on … 14 relevant papers.
    <boxed-text>
      <sec>
        <title>Summary points</title>
        <p>
          <list list-type="bullet">
            <list-item>
              <p>Longer consultations are … better patient outcomes</p>
            </list-item>
            <!-- ... -->
            <list-item>
              <p>Research on implementation is needed</p>
            </list-item>
          </list>
        </p>
      </sec>
    </boxed-text>
  </p>
Semantic complexity
Syntax is not the only site of complexity within XML
documents — semantic complexity also has a significant impact on
writing and working with XML. These two forms of complexity
often operate independently; as we saw above, relatively simple concepts
may require quite deep nesting. The reverse is also true — the
meaning expressed through markup might itself be complex or
deeply theoretical even if the encoding at stake is
straightforward. For instance, the Women Writers Project, a
longstanding TEI project focused on early women’s writing, uses
a custom <hyperDiv> element to contain features
that the WWP has identified as hypertextual.[5] These include
annotations, names spelled out in acrostic poems, invented
cast lists (for characters who speak within a drama but are not
included in the play’s printed cast list), and other phenomena that
operate hypertextually. <hyperDiv> is a single
element with a restricted set of permitted contents,[6] but it represents the WWP’s very particular theory of how texts
function as developed over decades of encoding pre-Victorian
women’s writing. <hyperDiv> may not add much to
the syntactic complexity of a document, but the semantic
complexity expressed through this theory of how texts function
is substantial.
Semantic complexity impacts XML project work because of
the time needed both to develop and to apply semantically rich
encoding practices. For example, the WWP collaborates with
editors Noelle A. Baker and Sandra Petrulionis on encoding the
Almanacks of Mary Moody Emerson for publication within the Women
Writers Online collection. Among the features represented in the
XML are Emerson’s famously capacious inclusions of other
authors’ language within her commonplace Almanacks. Most of
these are encoded with a custom <itg>
(intertextual gesture
) element, with greater specificity
provided through the @type attribute. In cases
where Emerson hews more closely to her source language,
<quote> and @type are used
instead. @source is also used to indicate the
source of the referenced text.[7]
The encoding at stake is relatively simple; each instance requires only one element
and two attributes.
A sample of this encoding is found in Figure 8.
Figure 8 Sample from the Women Writers Project XML encoding for
Emerson Almanacks showing the project’s use of
<itg type="dialogic_reference" source="mb:Fellowes_Picture">These
<choice><abbr>tho’ts</abbr><expan>thoughts</expan></choice> have passed my
<lb/>own mind in much the same connection.</itg>
<itg>.
|
allusion |
An implied or indirect, but deliberate, reference to another text |
|
dialogic reference |
Dialogue or direct address to authors or source material, or commentary on both in the form of debate, argument, or pondering/musing; or placement of authors in dialogue with each other |
|
distillation |
A synthesis of materials from a text or set of texts; may include direct quotation |
|
paraphrase |
A summary or representation of the meaning and content of material from another text that may or may not include some direct quotation of the original language |
|
reference |
A mention, typically brief, of material from another text |
|
repurposing |
A representation of material from another text that deliberately changes the meaning of the original |
@type attribute, this markup
expresses a semantically rich reading of Emerson’s multivalent
commonplacing practices. The simplicity of the syntax for this
encoding belies the rich editorial expertise that was necessary
to develop and apply this list of values.
Of course, it is also possible for syntactic and semantic
complexity to appear in tandem — our point here is
that one is not a predictor for the other. Perhaps the simplest
way to demonstrate this insight is to consider the possibility
that the same meaning might be expressed with completely
different markup. For instance, it is generally agreed that the
two encodings in Figure 9 are semantically
precisely the same.
Figure 9
<msg level="error"
     code="XTTE0570"
     text="An empty sequence is not allowed as the value of variable $fn"/>
  <msg>
    <level>error</error>
    <code>XTTE0570</code>
    <text>An empty sequence is not allowed as the value of variable $fn</text>
  </msg>
<placeName> means the same thing as the
<name> element with a value of place on
@type. The things that make
<placeName> harder or easier for an encoder to
understand are separate from the things that impact how long it
will take an encoder to type <placeName> or to
type <name> and add a @type
attribute and value. The syntactic complexity changes,
depending on which option is used, but the semantic complexity
stays the same.
For the kinds of complexity we are interested in — those that impact human work on XML projects — it is helpful to keep both semantic and syntactic complexity firmly in view. Moreover, we can broaden our view even further and consider the systems that surround XML documents. The next section discusses complexity within the processing, application, and versioning of XML files.
In the schema
Schemas, of course, can be complex (or not) themselves, may describe complex (or simple) XML languages, and may claim as valid various simple and complex instances. And it is not necessarily the case that simple schemas describe simple languages or that complex schemas describe complex languages, although both of those scenarios are not just possible, but outright likely.
But here is a demonstration of the opposite. Consider the
schema reproduced in Figure 10 (represented in RELAX NG compact syntax).
Figure 10 Figure 11
zero_or_more_in_alternation = ( a | b | c | d | e | f | g | h | i | j )*
start = element confusing { zero_or_more_in_alternation }
a = element a { zero_or_more_in_alternation }
b = element b { zero_or_more_in_alternation }
c = element c { zero_or_more_in_alternation }
d = element d { zero_or_more_in_alternation }
e = element e { zero_or_more_in_alternation }
f = element f { zero_or_more_in_alternation }
g = element g { zero_or_more_in_alternation }
h = element h { zero_or_more_in_alternation }
i = element i { zero_or_more_in_alternation }
j = element j { zero_or_more_in_alternation }
<?xml version="1.0" encoding="UTF-8"?>
<confusing>
  <a>
    <b>
      <c>
        <d>
          <e>
            <f>
              <g>
                <h>
                  <i>
                    <j/>
                  </i>
                </h>
              </g>
            </f>
          </e>
        </d>
      </c>
    </b>
  </a>
  <a>
    <b/>
  </a>
  <c>
    <d/>
    <a/>
  </c>
  <e>
    <c/>
    <f/>
    <i/>
  </e>
  <g>
    <a/>
    <h/>
    <b>
      <h/>
    </b>
  </g>
  <i>
    <j/>
  </i>
  <b>
    <c>
      <d>
        <a>
          <f/>
          <g/>
          <e/>
          <i/>
          <h/>
        </a>
        <j/>
        <b/>
      </d>
    </c>
    <e>
      <f>
        <h>
          <g>
            <e/>
          </g>
        </h>
      </f>
      <a/>
      <b>
        <j>
          <h/>
        </j>
        <e/>
      </b>
    </e>
  </b>
</confusing>
It is interesting to consider the case of a schema expressed
in XML (e.g., RELAX NG or XSD; or XML-Data, XDR, DCD, SOX, XDUCE,
TREX, etc.; or even Schematron or X-Definition, we
suppose) — does measuring any of the simple
counts
or averages tell us anything about the complexity of either the
schema or the instances that conform to it? We suspect the answer
is that while there is some loose correlation, there is no cause and
effect relationship. However, we do not investigate this question
further in this paper.
A schema may also make things more complex by defining two
different syntactic structures that convey the same
semantics. Many languages, for example, allow either an attribute
or a child element for the same concept (The ant
build.xml file allows this often, but as far as we can tell there
is no schema for it.) For example, in TEI a person’s name might be
encoded using an <rs>, a <name>,
or a <persName> element. While there are
advantages to this flexibility, it adds complexity to the schema
itself and to any generic processor.
Tommie Usdin hit this particular nail on the head in 2002:
I remember a table model … that allowed users to model a table as either a series of rows that contained cells (implicitly creating columns) or as a series of columns which contained cells (implicitly creating rows). … the specification … allowed either encoding because they were logically equivalent and there was no rational reason to require people to use one or the other. From either encoding the same matrix could be constructed for display or computation and the guidelines did not want to be unnecessarily restrictive. … So this meant that I could receive the same data in dramatically different sequences and had to know that it was the same. This meant that there were not guidelines on which to use, and that tools that were to read, process, even compare document content had to be very complex. This was not cool. It was putting an unreasonable burden on text encoders (deciding which orientation to use without guidance) and an onerous burden on those intending to receive content from several sources and re-use it.
It is worth noting that human schema authors will often put effort into making their schemas less complex, sometimes even at the expense of allowing the schema to be somewhat looser or stricter than would be preferred. Thus there is often a trade-off between complexity in the schema vs the risk of complexity in the instances.
On the other hand, schemas generated by software, at least those generated by current software systems like the TEI’s oddbyexample or oXygen’s Generate/Convert Schema, tend to be more complicated than that which a human author would generate. Whether the valid instances described by such a generated schema may be more complex than desired or not is in large part a function of the desired complexity.
Extreme schemas
Consider the encoded poem in Figure 12 which is
a mild simplification of one which we use in our introduction
to encoding classes.
Figure 12
<?xml version="1.0" encoding="UTF-8"?>
<lg type="limerick" rhyme="aabba" n="3">
  <head>Warp Speed, Ms Bright!</head>
  <l>There was a young lady named Bright,</l>
  <l>Who traveled much faster than light,</l>
  <l>She departed one day,</l>
  <l>In a <term xml:id="t17">relative</term> way,</l>
  <l>And returned on the previous night.</l>
  <note target="#t17">See
    <ptr target="http://en.wikipedia.org/wiki/Theory_of_relativity"/>.</note>
</lg>
write a RELAX NG (compact syntax) schema
that validates the poem in Figure 12,
one
can easily imagine that a human might write a schema that would
validate the above document or any similar document, i.e., one
that contained a limerick preceded by a heading or title, either
of which might contain technical terms glossed with footnotes,
and for which the rhyme scheme may be encoded explicitly,
etc. For a sample of one such, see Figure 13.
But similarly, one can imagine that either a human or
software program might generate a schema that would accept as
valid any XML file that used any combination of
<head>, <lg> (line group),
<l> (metrical line), <term>,
<note>, and <ptr> elements, each
which may have none or all of @label,
@n, @rhyme, @target,
@type, or @xml:id. For a sample of
such, see Figure 14. Such a schema is not much better
than useless for a project trying to encode poetry.
Conversely one can imagine that either a human or software
program might generate a schema that would accept as valid
pretty much only the sample document. For a sample of such, see
Figure 15. We believe such a
1-document
schema is utterly useless for a
project trying to encode limericks, as evidenced by the lack of
any such schemas in existence.
Figure 13: limerick schema 1: Reasonable
start = lg
lg = element lg {
  attr.type?,
  attr.rhyme?,
  attr.n?,
  head?,
  l, l, l, l, l,
  note*
  }
attr.type = attribute type { token }
attr.rhyme = attribute rhyme { token }
attr.n = attribute n { xsd:nonNegativeInteger }
head = element head { stuff }
l = element l { stuff }
term = element term { text }
ptr = element ptr { target, empty }
note = element note {
  target,
  stuff
  }
target = attribute target { xsd:anyURI }
stuff = ( text | term | note | ptr )*
An at least somewhat reasonable schema for limericks
Figure 14: limerick schema 2: Extremely loose
start = lg
lg =     element lg    { attrs, ( text | lg | head | l | term | note | ptr )* }
head =   element head  { attrs, ( text | lg | head | l | term | note | ptr )* }
l =      element l     { attrs, ( text | lg | head | l | term | note | ptr )* }
rhyme =  element rhyme { attrs, ( text | lg | head | l | term | note | ptr )* }
term =   element term  { attrs, ( text | lg | head | l | term | note | ptr )* }
note =   element note  { attrs, ( text | lg | head | l | term | note | ptr )* }
ptr =    element ptr   { attrs, ( text | lg | head | l | term | note | ptr )* }
attrs = ( attr.type, attr.rhyme, attr.n, attr.target )
attr.target = attribute target { text }?
attr.type =   attribute type   { text }?
attr.rhyme =  attribute rhyme  { text }?
attr.n =      attribute n      { text }?
An extremely loose schema against which the sample limerick, and all sorts of bizarre encoding, is valid
Figure 15: limerick schema 3: Extremely strict
start =
  element lg {
    attribute type { "limerick" },
    attribute rhyme { "aabba" },
    attribute n { "3" },
    element head { "Warp Speed, Ms Bright!" },
    element l { "There was a young lady named Bright," },
    element l { "Who traveled much faster than light," },
    element l { "She departed one day," },
    element l {
      mixed {
        element term {
          attribute xml:id { "t17" },
          "relative"
        }
      }
    },
    element l { "And returned on the previous night." },
    element note {
      attribute target { "#t17" },
      mixed {
        element ptr {
          attribute target {
            "http://en.wikipedia.org/wiki/Theory_of_relativity"
          }
        }
      }
    }
  }
An extremely strict schema for the given limerick
In the system
Processing complexity
In many cases markup that is syntactically simple can be quite difficult to process. Soft hyphens, for example, are not particularly difficult for humans to mentally process, and are very easy to encode. But to resolve them while leaving surrounding markup intact is extraordinarily difficult (Bauman (2016)).
In many cases, markup is deliberately made more complicated in order to diminish the complexity of processing. Consider the simple case of transcribed dates. While providing a standardized version of the date in the encoding makes that encoding more complicated, it can make processing much easier, or, in cases of ambiguity, possible.
In Figure 16, the use of the TEI
Figure 16 Excerpt of the Women Writers Project XML encoding for
Williams showing two different date
formats used in the same paragraph.
@when attribute means that a processor which needs
to, say, sort dates or put them on a timeline does not have to
be able to parse both of the formats that Catherine Williams
uses in a single paragraph of her Biography of
Revolutionary Heroes.
<p>The first wife of <persName>Captain Olney</persName>, and mother of
  <lb/>his children, died on
  <date when="1813-12-13">13th of <name>December</name> 1813</date>.
  …
  On <date when="1830-03-25"><name>March</name> 25th,
  <lb/>1830</date>, he addressed the following letter to … </p>
While we concede that it is not all that difficult write
code that differentiates between those two formats and will
parse either, the point is that a) a small increase in
complexity of the XML can significantly decrease complexity of
the processor, and, more importantly b) this added complexity
also resolves any ambiguity. E.g., 3/4/1797
is ambiguous: it
might indicate 04 March 1797, when George Washington peacefully
relinquished his role as the first President of the United
States to John Adams, ushering in a 223¾-year span of peaceful
transfer of power in the USA; or it might indicate 03 April
1797, when in a letter to James McHenry he wrote We get so many
details in the Gazettes, and of such different complexions, that
it is impossible to know what credence to give to any of
them.
(Washington letter)
Sometimes, though, the reverse is the case: XML users
sometimes tolerate or place heavy burdens on the processing in
order to keep the markup simple. We think the
Figure 17@select attribute of XSLT is a marvelous
example. Consider <xsl:sequence select="if ( $title eq
'') then string-join( distinct-values(
rdf:Description/System:Directory ), ', ') else translate(
$title, '_',' ')"/> The syntax of the XML is dead
simple: an empty element (in a particular namespace) with one
attribute (in no namespace). All the complexity is inside the
one attribute. XSLT did not have to be designed that way; it
could have been designed to minimize the work needed to parse
and thus process the XPath, at the cost of adding complexity to
the XML structures used. In which case, that <xsl:sequence>
might look something like Figure 17.
  <xsl:sequence>
    <xp:if>
      <xp:test>
        <xp:varRef name="title"/>
        <xp:binop name="equals"/>
        <xp:string/>
      </xp:test>
      <xp:then>
        <xp:function name="string-join">
          <xp:arg n="1">
            <xp:function name="distinct-values">
              <xp:arg n="1">
                <xp:path>
                  <xp:step axis="child">
                    <xp:ref type="element" ns="http://www.w3.org/1999/02/22-rdf-syntax-ns#" name="Description"/>
                  </xp:step>
                  <xp:step axis="child">
                    <xp:ref type="element" ns="http://ns.exiftool.org/File/System/1.0/" name="Directory"/>
                  </xp:step>
                </xp:path>
              </xp:arg>
            </xp:function>
          </xp:arg>
          <xp:arg n="2">
            <xp:string>, </xp:string>
          </xp:arg>
        </xp:function>
      </xp:then>
      <xp:else>
        <xp:function name="translate">
          <xp:arg n="1">
            <xp:varRef name="title"/>
          </xp:arg>
          <xp:arg n="2">
            <xp:string>_</xp:string>
          </xp:arg>
          <xp:arg n="2">
            <xp:string> </xp:string>
          </xp:arg>
        </xp:function>
      </xp:else>
    </xp:if>
  </xsl:sequence>
Another example of shifting the burden of complexity to
processing is a project that permits the content of
<persName> to be in either surname, given_name
order or given_name surname
order. This may make life easier
for the encoder, but now requires processors to figure out and
parse the format.
In TEI P5, the elements used to mark cases in which an
addition or deletion, damage to the writing surface, or any one
of various other manuscript interventions span across other XML
hierarchical boundaries use a @spanTo attribute on
an empty element (e.g., <delSpan
spanTo="#del03end"/>) to point to the end of the
feature at stake. But the element pointed to can be any element, most
commonly an <anchor>. This may make less work
for an encoder, but it also makes work for the proofreader a bit harder,
makes work for the processor that is dealing with the overlap problem
from the start of the overlapping virtual element mildly more
difficult, and makes it very difficult for a processor to work
on an overlap problem from the end of the overlapping virtual
element. (This becomes more readily apparent when you consider
that the portion of XML being handed to the processor may not be
the entire document.)
One way to look at complexity of markup within a
processing ecosystem is to (arbitrarily, we admit) divide both
into high and low, for lack of a better word,
Figure 18 Figure 19precision.
More precise markup not only chops the
text up into smaller bits, but also asserts what those bits are,
semantically. Less precise markup leaves more parsing and
semantic creativity to the processing. So, for example, Figure 18
is quite precise, whereas Figure 19 is
somewhat less so.
<l>Whil'<choice><sic>f</sic><corr>ſ</corr></choice>t the fair Nymphs Eyes apace</l>
<l><choice><sic>Whil'ft</sic><corr>Whil'ſt</corr></choice> the fair Nymphs Eyes apace</l>
It is our assertion that, with exceptions, and presuming that the desired processing matches the encoding, Table I represents the general case.
Table I
| markup ⇓ / desired processing ⇒ | low precision | high precision |
| low precision | simple | complex |
| high precision | complicated by the need to strip some encoding[9] | simple |
Another example of low precision encoding occurs within
the TEI with its teidata.authority datatype. The value of this
datatype may be either a) any URI that does not contain a space,
or b) a single string composed of one or more characters other
than those with a Unicode property of Space or Other. If the
value is a URI it is a pointer that should be followed, and if
it is a string its meaning should be defined in the TEI
customization. But since the only characters allowed in a URI
are the digits 0–9, the letters A–Z
and a–z, and the characters
:?#/+-.@_~[]!$&'*,;=, none of which have the
Unicode property Other,
any URI is also
allowed as a string that meets the criteria. I.e., an
application cannot, in general,
differentiate which it is being handed. While it is true that at
any given project it is almost guaranteed that those writing
code to read the TEI files will be able to tell easily which is
which, a generic processor that is supposed to be able to read
in any TEI file is stuck. (Being able to read the schema may get
it unstuck, though.)
An example of syntactically simple markup that is
semantically ambiguous (and thus complex) is the TEI
<q> element, especially in TEI P3 & TEI P4
which explicitly asserted that <q> could be used
for words or phrases attributed to other voices within the
current work
while <quote> would be used for
passages cited from other works
; or <q> might
be used for both purposes. So a generic processor reading a P3
or P4 document that has <q> elements but no
<quote> elements has no idea whether the
document happens not to have any passages cited from other
works, or if it does have some, how to discriminate them from
passages attributed to other voices. The P3 & P4 Guidelines
recommend that The editorial policy in this respect should be
stated in the encoding description of the TEI Header,
but do
not say where in the <encodingDesc> this
information should be put. What would seem the obvious choice,
encodingDesc/editorialDecl/quotation, is about the
quotation marks, not what the quotation elements are used
for.
Application complexity
In some cases, complexity may manifest when XML encoding is
applied to data. That is, the markup at stake may not be particularly
dense, and it may not involve especially thorny semantic
conceptualizations, but the application of that markup to human
languages may itself prove complex. For example, the TEI’s
Figure 20<placeName> (place name) element is defined
briefly enough in the Guidelines as: contains an absolute or
relative place name
(TEI <placeName>). While more
detailed markup is possible, <placeName> can be
applied quite simply, as in Figure 20.
<placeName>Haverhill</placeName>
<placeName>, it’s used to tag names of places, and
it doesn’t require any additional layers.
However, the application of <placeName> can
raise complex questions. For instance:
-
How to handle names of places that have more than one level of specification (is
Sanbornville, New Hampshire
one place name or two?) -
How to handle anonymized place names (is
Mount —
the name of a place? What about just—
?) -
How to handle combined place names (If
North and South Hampton
should be tagged as two places, is the name of the first town simplyNorth
?) -
How to handle abbreviated place names (
N. York
might reasonably be a place name, but what about something likeshe could walk to the Seminary in only 30 minutes
as an abbreviation forthe Exeter Female Seminary
?) -
How to handle cases where it is unclear from context whether a text is referencing a place entity or an organization entity? (What to do with
Eleanor went to Dartmouth
if we can’t know whether Eleanor drove to the town or matriculated at the college?) -
How to handle abstract, religious, or fictional places (is Heaven a place, whether on Earth or otherwise?)
Version complexity
Finally, complexity may manifest in the systems that surround XML documents through a file’s version histories. Here, again, the density of the XML files themselves can be quite separate from complexity within systems for creating or using those files. Imagine, for instance, a file that was:
-
created in SGML and later converted to XML,
-
updated through multiple different encoding systems and new practices over a project’s history,
-
revised and re-encoded to correct significant errors in the original markup, and
-
initially conceived of as multiple documents but later combined into one (or vice versa).
<change> element, which documents a change … made during … the revision of an electronic file(TEI <change>). We could also compare versions of the files themselves — any files that demonstrate significant differences between the current iteration and the originally completed copy are likely sites of version complexity.
As we are seeing, an examination of these extra-documentary sources of complexity can provide a fuller picture of the ways that complexity impacts the operations of an encoding project. In the next section, we will explore complexity as perceived by the humans creating and interacting with XML files.
In your brain
One final location of complexity exists inside the minds of the humans interacting with XML files. Complexity within XML files is highly perspectival for human readers — the more familiar individuals are with the markup systems at stake, the less significant both semantic and syntactic complexity are likely to seem. There are some upper thresholds on this phenomenon. Systems that have very large numbers of element types will need to contend with the fact that most human encoders can keep only so many encoding features in their heads at any given time. If a project is applying hundreds of different element types, they will have to help encoders to remember that those hundreds of element types exist. Of course, this is one of the reasons that measurements of syntactic complexity care about things like the number and diversity of element types in a file or corpus. Along the same lines, applications involving semantic complexity are challenging precisely because they require human encoders to parse fine degrees of nuance repeatedly and consistently.
For an example of a particularly human experience of
complexity, we can consider visual
complexity. Indentation and whitespace can have a
dramatic impact on how readable files are to humans. But forms of
whitespace that are usually meaningless to a program
nevertheless can render documents all but unreadable to some
people. From a computational perspective, whether or not format
and indent
has been applied to a document generally has
no impact on its complexity. From a human perspective,
files with unconventional or inconsistent whitespace will often
feel much more complex.[12]
If one is interested in predicting or containing complexity’s impacts on a project’s work practices, sustainability, and productivity, then the forms of complexity that occur within human brains cannot be ignored. In the next section, we consider some ways that human experiences of complexity are interestingly or usefully distinct from purely computational ones.
Complications of complexity
Now that we have established an inventory of the many sites at which complexity impacts XML projects, let us situate some actual encoding practices within this framework. Here, we will focus on instances where the obvious forms of syntactic complexity are not what makes markup difficult to work with.[13] We will examine the forms of complexity that increase human time needed for:
-
writing documentation (for encoders, for programmers, for readers),
-
data capture,
-
proofing and reading XML data, and
-
processing XML files.
Our analysis is situated within the perspective of digital humanities project work — and TEI encoding in particular — and we are far from being able to offer any Grand Unified Theory of XML Complexity. But we do hope our work can help move XML studies toward a more complete understanding of complexity so that projects will be better able to predict and manage its impacts on their work.
Case study: project management and renditional defaults
TEI projects often wish to provide information about the
rendition, or appearance, of the source texts they encode. There
are several mechanisms within TEI for providing this
information — the sample in Figure 21
shows five examples of the @rend attribute.
Figure 21 Sample from the Women Writers Project XML encoding for
Bryan showing the project’s use of the TEI
<epigraph rend="post(#rule)align(left)indent(1)">
  <quote rend="pre(“)post(”)" source="b:IT02328.4" xml:id="q001">
    <lg type="indeterminate">
      <l>—All beneath th' unrivall'd rose,</l>
      <l>The lowly daisy sweetly blows;</l>
      <l>Tho' large the forest monarch throws</l>
      <l rend="indent(2)">His army shade,</l>
      <l>Yet green the juicy hawthorn grows,</l>
      <l rend="indent(2)">Adown the glade.</l>
    </lg>
  </quote>
  <bibl rend="align(right)case(smallcaps)" source="b:IT02328.4" xml:id="b001">
    <author><persName ref="p:rburns.fgh">Burns</persName></author>.
  </bibl>
</epigraph>
@rend attribute to record information about the
appearance of the source text.
The WWP uses what are called rendition
ladders
in which each rung
is a keyword
immediately followed by zero or more arguments in
parentheses. For example, the ladder for the
<bibl> element in Figure 21 has
the align keyword with an argument of
right and the case keyword with an
argument of smallcaps. This system allows the WWP
to provide detailed information about the appearance of the
texts in the Women Writers Online collection.[14] As the example above suggests, this
markup also adds substantial syntactic and operational
complexity. Since rendition ladders can be quite verbose, this
encoding requires several proofing passes,[15] and processing
encoded files for publication requires the software to be able
to parse the syntax of the rendition ladders and act
accordingly.
Even with simpler mechanisms for specifying rendition, the
textual phenomena at stake are diverse (in terms of the number
of renditional features that projects may choose to encode) and
frequent (in terms of the numbers of instances in each document)
enough that many projects will experience challenges similar to
the WWP’s. From a syntactic perspective, then, renditional
encoding can make a project’s markup much more complex. One
mitigating factor is that rendition is often repeated
consistently on the same textual phenomena. For example,
quotations and spoken dialogue may be enclosed in quotation
marks for all or most of the instances within a file, the first
lines of paragraphs may be indented, and headings may be aligned
center. Thus, it is possible for projects to provide information
about rendition at the document — or even
project — level, rather than the instance
level. The TEI provides a Figure 22<rendition> element
that supplies information about the rendition or
appearance of one or more elements in the source text
(TEI <rendition>). This element is contained in a
<tagsDecl> (tagging declaration
)
element that is itself contained within the
<teiHeader> with other metadata. This allows an
encoder to specify a default rendition for all the elements (or
combinations of elements and attributes) within a file. For
instance, the encoding in Figure 22 is how the
three examples noted above would be expressed within the WWP’s
files.
  <tagsDecl>
    <rendition selector="p">first-indent(1)</rendition>
    <rendition selector="quote, said">pre(“)post(”)</rendition>
    <rendition selector="head">align(center)</rendition>
  </tagsDecl>
aling(center) on occasion are drastically reduced (and
easier to fix) when it is only typed once instead of hundreds of
times, and an encoder cannot inadvertently start using
indent(1) when they mean
first-indent(1) halfway through a file.
With a focus on pure syntax, renditional
defaults clearly reduce complexity.
However, renditional defaults substantially increase
operational complexity. One key aspect of renditional defaults
is that they remain in force whether or not the
encoder — or any subsequent readers and
proofreaders of the document — remembers they are
there. For encoders, this means that they must remember any
defaults they have set and override these locally wherever the
default is not accurate. It can be harder to encode things that
are not there than things that are — noting and
encoding the presence of indentation requires a different kind
of attention than noting and responding to its
absence.[16] That is, even though renditional
defaults reduce the work necessary for encoding, they also
complicate the encoding task. And, the same is true for anyone
else who interacts with the document. Imagine a proofreader who
corrects a mis-encoded <label> to a
<head>; they will have to check the renditional
defaults to make sure that these match the instance they are
correcting. Any changes to elements within a project that uses
renditional defaults will require such verification.
Renditional defaults can dramatically reduce the amount of markup within documents, but they also double the time necessary to locate and thereby act on any revisions that involve rendition or that require changes to the elements in a file. Removing local encoding also complicates the retrieval of information through XPath and related operations. For instance, if a project manager wishes to review all of the instances in which certain elements are italicized, they will need to take renditional defaults into account. And, of course, renditional defaults must also be handled when processing texts for publication or other purposes. In many ways, renditional defaults do not reduce complexity, but instead move it from a project’s encoders to its developers and project managers.[17]
Our point here is not that renditional defaults cause more problems than they solve — this is manifestly not true. Instead, we wish to use renditional defaults to illuminate the ways that different forms of complexity interact with each other in a project’s work environment. Renditional defaults decrease syntactic complexity, but increase complexity within systems for proofing and processing documents, as well as within the minds of human encoders and proofers. Thus, if one wishes to measure complexity with attention to predicting its impact on the full range of a project’s publication processes, one must look beyond syntax.
Case study: sequence vs containment
In almost all cases in TEI, information items are
associated with each other through XML containment. E.g., if you
were reading the TEI-encoded version of the credits to
Toy Story 2, you would likely find something
like Figure 23.
Figure 23
  <respStmt>
    <persName>Ronen Barzel</persName>
    <resp>animation software engineer</resp>
  </respStmt>
animation software engineer
is
associated with the name Ronen Barzel
is indicated by the XML
hierarchy — the elements in question are siblings,
children of the same parent. If you had found the
<persName> for Ronen, to determine what he did you
would ask for ../resp. There is (almost) no danger
that having found Ronen’s name a program would inadvertently
extract the <resp> associated with Michael
Shantzis (software engineer) or Gaylin Susman (supervising
technical director).
However, the TEI handles Figure 24<publicationStmt>
quite differently from <respStmt>. If this paper
had been written in TEI (as opposed to the Balisage tagset 1.5,
and thus a subset of DocBook 5.0CR7) the publication statement
would likely list Balisage as the publisher, but also the Women
Writers Project as a separate distributor, as seen in Figure 24.
      <publicationStmt>
        <publisher>Balisage</publisher>
        <idno type="fn">Bal2026con0503</idno>
        <idno type="DOI">10.4242/BalisageVol31.Connell01</idno>
        <date when="2026-10-01"/>
        <distributor>Northeastern University Women Writers Project</distributor>
        <address>
          <addrLine>SL 371</addrLine>
          <addrLine>Northeastern University</addrLine>
          <addrLine>360 Huntington Avenue</addrLine>
          <addrLine>Boston, MA  02115-5005</addrLine>
          <addrLine>USA</addrLine>
          <addrLine>url:mailto:wwp@northeastern.edu</addrLine>
        </address>
        <date when="2026-12-11"/>
      </publicationStmt>
<publisher>, <distributor>, or
<authority>. So in the above example the
<idno> elements are associated with the
<publisher>, but the <address> is
not; it is associated with the
<distributor>. Thus, having found an
<address>, <date>, or
<idno>, to find out which entity it is associated
with, you would ask for
(preceding-sibling::publisher|preceding-sibling::distributor|preceding-sibling::authority)[1]. While
this is not particularly difficult, it is mildly more complicated
than would be the case if containment instead of sequence were the
organizing principle, in which case you would ask for something
like ../name.
We are not claiming that
using sequence as an organizing principle is so much more
complicated that documents become complex. We do claim that using
both methods of association for similar kinds of data in the same
document makes almost every stage of document
production — training, documentation, data capture,
processing — just that much more difficult. This is
similar to the problem of reading large chunks of center-justified
text. When reading, the human eye wants to pop
from
the end of one line right back to the same horizontal position as
it was before. That is, in a left-to-right written language such
as English, it is easier to read left-justified text; in a
right-to-left written language such as Arabic, it is easier to read
right-justified text.
The fact that TEI uses both methods of association demonstrates that TEI in particular, and (we claim) markup languages in general, are also social phenomena: they are constructed by individuals or groups of people over time, and they reflect that history. The TEI’s use of both sequence and containment does add some complexity for processing documents, training new encoders, etc., but it also reflects the language’s history. And, while the TEI has continued development at its heart, a change to this practice would itself cause some downstream complexity for those who have become used to the current system. (That said, the authors do actually think this is a change the TEI should make (Bauman & Connell (2026)).) This is just another way of showing how you need to keep the full system in mind when you are thinking about complexity.
It is worth noting that the ISO workgroup that maintains Schematron is considering switching Schematron Validation Report Language (SVRL) from sequence-based to containment-based (Sales (2026)).
Comparing human assessment of complexity with syntactic metrics
While we have argued here that syntactic measures cannot
provide a full picture of the impacts that complexity will have on a
project’s use of XML, we are also interested in the ways that syntax
interacts with other forms of complexity, especially complexity as
experienced or perceived by humans. The 2026 Balisage conference
itself was an excellent opportunity to learn more about how humans
perceive complexity, and our presentation thus included an
experiment
during which we asked the audience to weigh in on the
complexity of several source documents. We shared five sample
documents and asked participants to rank these by complexity, based
solely on a visual review of the texts — that is,
without using XPath or other methods for direct measurement. Since
we expected that participants would find more familiar markup languages
less complex (even if asked to set aside personal familiarity for
the moment), we selected from a range of languages: JATS, DITA,
DocBook, Akoma Ntoso, and TEI. The survey asked participants to rank
the five samples from least to most complex, and generated scores
for each sample: from 1 for the least to 5 for the most complex.
Averaged summary scores assigned by session participants are presented in
Table II.
Table II
Average of all 31 participant complexity scores
| Language | Avg Score |
| Akoma Ntoso | 4.097 |
| TEI | 3.290 |
| JATS | 3.258 |
| DITA | 2.387 |
| DocBook | 1.968 |
We also asked participants to comment on how familiar they were with each language, selecting from the following options:
-
I’ve never seen this language
-
I’ve seen it before
-
I’ve used it a few times
-
I use it regularly
-
I helped write the spec
Table III
Average of all 30 participant[18] familiarity scores
| Language | Avg Score |
| DocBook | 3.00 |
| TEI | 2.63 |
| JATS | 2.60 |
| DITA | 2.50 |
| Akoma Ntoso | 1.67 |
Figure 25
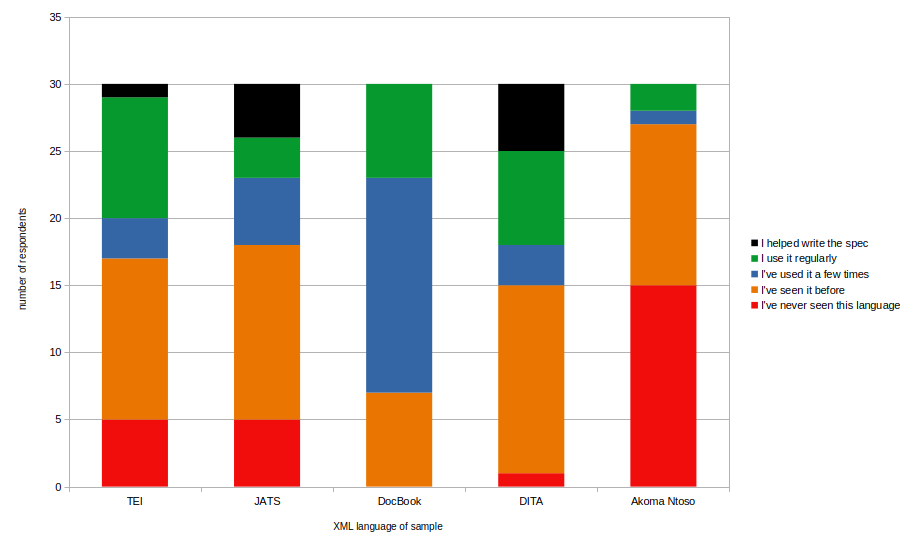
A column chart that shows, for each of the five sample XML languages, the number of each familiarity level indicated by the 30 respondents who answered this question.
The scare quotes around the word experiment
above should not be taken lightly — this was by no
means a rigid, well-controlled, scientific experiment. Among the
glaring shortcomings are that our five sample files were a
convenience sample; we had only 31 responses, all collected by the
end of our conference session; and asking participants to rank the
samples, rather than assign each a complexity score, flattened some
nuances in service of supporting comparison with the syntactic
metrics we calculated for our samples.
Regarding those metrics, we developed a set of 31 candidate
measures of syntactic complexity; calculations like average
number of element instances per element type
and
number of element instances plus attributes per KiB of
filesize.
Prior to the conference presentation we had
generated a table that included the scores for each of the 31
candidate measurements for each of the five files (using this
stylesheet). After collecting the ranking of sample files
from the audience, we compared it to each of the 31 rankings
obtained by our candidate measurements (which are summarized in
Table IV), and found that none of the
rankings from our candidate measurements matched that of the humans
in the audience.[19]
Table IV
Sum of all 31 candidate metrics
| Language | Score |
| DocBook | 169.58 |
| Akoma Ntoso | 140.82 |
| DITA | 128.88 |
| TEI | 128.18 |
| JATS | 112.48 |
Interestingly, the two samples with the highest scores on the syntactic complexity metrics were at opposite ends of the participants’ rankings: the DocBook sample was ranked as least complex and the Akoma Ntoso one as most complex. It seems clear that language familiarity is playing a role here, as DocBook was also ranked the most familiar language. That said, we also found that there are some notable differences between the complexity scores that participants assigned and their reported familiarity with each language. For instance, TEI was marked the second most complex example, but it was also the second most familiar language. Familiarity scores for TEI, JATS, and DITA were very close, but the DITA sample was marked by participants as much less complex than the other two. Conversely, TEI and DITA have near identical complexity scores by the syntactic metrics (128.18 and 128.88, respectively), while JATS scores somewhat lower (112.48). Correlations seem to fall at the ends of the spectrum: Akoma Ntoso is markedly the least familiar language (according to the responses we received) and was also identified as the most complex sample. Similarly, DocBook was the most familiar language and identified as the least complex sample.
These results become even more striking when one examines the distribution of responses for each language — 50% of respondents reported that they had never seen Akoma Ntoso before, while no respondents said the same of DocBook. On the other hand, 76.6% of participants reported that they had used DocBook at least a few times, if not regularly; only 10% reported the same for Akoma Ntoso. We don’t want to read over-broadly into these results, given the limitations discussed above, but we might be seeing some evidence that the degree of familiarity a person has with a language — in the sense of whether they are an occasional or regular user — has less of an impact than whether the language is totally unfamiliar — in the sense that an XML language will seem more complex when a person is seeing it for the first time.
Concluding thoughts
While there clearly must be a line between simplicity and complexity, it is also clear that to a large extent what will be considered complex (particularly as opposed to complicated) differs from person to person. We have demonstrated here, though, that complexity comprises all sorts of issues in addition to straight-forward syntactic complexity, including the complications involved in applying semantics to markup (both at the stage of initial capture and on reading or processing the marked-up document), constraining markup, processing documents, and reading (by humans of) encoded files.
We have argued herein that syntactic measures cannot provide a full picture of the impacts that complexity will have on a project’s use of XML. We have also demonstrated that the relationship between raw syntactic complexity and complexity as perceived by humans is at best non-trivial to establish. Despite the challenges posed by this problem space, we hope that the frameworks outlined in this paper might make it possible for future researchers to continue addressing the thorny question of how both humans and computers interact with XML complexity — and, even more so, we hope that we have shown how important it is for XML projects to understand the manifold causes of complexity.
References
[Basci & Misra (2009)] Basci, Dilek and Sanjay Misra. “Measuring and Evaluating a Design Complexity Metric for XML Schema Documents.” Journal of Information Science & Engineering 25 (2009): 1405–1425. doi:https://doi.org/10.6688/JISE.2009.25.5.7.
[Bauman (2016)] Bauman, Syd. “The Hard Edges of Soft Hyphens.” Presented at Balisage: The Markup Conference 2016, Washington, DC, August 2 - 5, 2016. In Proceedings of Balisage: The Markup Conference 2016. Balisage Series on Markup Technologies, vol. 17 (2016). doi:https://doi.org/10.4242/BalisageVol17.Bauman01.
[Bauman & Connell (2026)]
Bauman, Syd and Sarah Connell. Reducing interoperability with
(unnecessary?) complexity.
Presented at TEI 2026
Creating Connections, Unsettling Practices, Vancouver, BC,
August 13, 2026.
[Beale et al. (2024)]
Beale, Dean, Francesco Dazzi, and Theo Tryfonas. Unweaving the
Definitions of Complexity.
IEEE Transactions on
Systems, Man, and Cybernetics: Systems 54 (2024):
682-692. doi:https://doi.org/10.1109/TSMC.2023.3300753.
[Bryan] Bryan, Mary. Sonnets and Metrical Tales, 1815. Northeastern University Women Writers Project, 22 Aug. 2008. https://www.wwp.northeastern.edu/texts/bryan.sonnets.html. [Original source: Bryan, Mary. Sonnets and Metrical Tales, Bristol City Printing Office, 1815. British Library catalogue 992.i.13(4); ALMA 990148163560109251.]
[Emerson Almanacks] Emerson, Mary Moody. Almanacks, 1804-1858. Edited by Noelle A. Baker and Sandra Harbert Petrulionis. Northeastern University Women Writers Project, 16 June 2026. https://www.wwp.northeastern.edu/texts/emerson.almanack.html. [Original source: Emerson, Mary Moody, 1774–1863. [Almanac] A.MS. MS Am 1280.235 (385). Emerson family papers, 1699–1939, Houghton Library, Harvard University.]
[Finegold (2022)] Finegold, Diane. “Complex versus Complicated.” Complex Systems Frameworks Collection. 2022. https://www.complexsystemsframeworks.ca/framework/complex-versus-complicated/.
[Ruellan (2012)] Ruellan, Hervé. “XML Entropy Study.” Presented at Balisage: The Markup Conference 2012, Montréal, Canada, August 7–10, 2012. In Proceedings of Balisage: The Markup Conference 2012. Balisage Series on Markup Technologies, vol. 8 (2012). doi:https://doi.org/10.4242/BalisageVol8.Ruellan01.
[Sales (2026)] Sales, Andrew. “SVRL 2.0: A new beginning?” Presented at XML Prague, 2026, Prague, Czech Republic, June 4–6, 2026. https://andrewsales.com/slides/SVRL%202.0.pdf.
[Sperberg-McQueen (2021)] Sperberg-McQueen, C. M. “Catastrophic complexity.” Presented at Balisage: The Markup Conference 2021, Washington, DC, August 2–6, 2021. In Proceedings of Balisage: The Markup Conference 2021. Balisage Series on Markup Technologies, vol. 26 (2021). doi:https://doi.org/10.4242/BalisageVol26.Sperberg-McQueen02.
[Stührenberg & Wurm (2010)] Stührenberg, Maik and Christian Wurm. “Refining the Taxonomy of XML Schema Languages. A new Approach for Categorizing XML Schema Languages in Terms of Processing Complexity.” Presented at Balisage: The Markup Conference 2010, Montréal, Canada, August 3–6, 2010. In Proceedings of Balisage: The Markup Conference 2010. Balisage Series on Markup Technologies, vol. 5 (2010). doi:https://doi.org/10.4242/BalisageVol5.Stuhrenberg01.
[TEI <change>] TEI Consortium, eds. “Appendix C.1 <change>.” TEI P5: Guidelines for Electronic Text Encoding and Interchange. 4.11.0. 2026-02-18. TEI Consortium. https://www.tei-c.org/Vault/P5/4.11.0/doc/tei-p5-doc/en/html/ref-change.html (2026-04-03).
[TEI <placeName>] TEI Consortium, eds. “Appendix C.1 <placeName>.” TEI P5: Guidelines for Electronic Text Encoding and Interchange. 4.11.0. 2026-02-18. TEI Consortium. https://www.tei-c.org/Vault/P5/4.11.0/doc/tei-p5-doc/en/html/ref-placeName.html (2026-04-03).
[TEI <rendition>] TEI Consortium, eds. “Appendix C.1 <rendition>.” TEI P5: Guidelines for Electronic Text Encoding and Interchange. 4.11.0. 2026-02-18. TEI Consortium. https://www.tei-c.org/Vault/P5/4.11.0/doc/tei-p5-doc/en/html/ref-rendition.html (2026-04-03).
[Usdin (2002)] Usdin, Tommie. “When ‘It Doesn’t Matter’ means ‘It Matters’.” Presented at Extreme Markup Languages® 2002, Montreal, QC. https://www.researchgate.net/publication/221211432_When_It_Doesn't_Matter_means_It_Matters/link/605cb97a92851cd8ce692358/download?_tp=eyJjb250ZXh0Ijp7ImZpcnN0UGFnZSI6InB1YmxpY2F0aW9uIiwicGFnZSI6InB1YmxpY2F0aW9uIn19.
[Washington letter] “George Washington to James McHenry, 3 April 1797,” Founders Online, National Archives, https://founders.archives.gov/documents/Washington/06-01-02-0051. [Original source: The Papers of George Washington, Retirement Series, vol. 1, 4 March 1797 – 30 December 1797, ed. W. W. Abbot. Charlottesville: University Press of Virginia, 1998, pp. 71–72.]
[Williams] Williams, Catherine Read (Arnold). Biography of revolutionary heroes; containing the life of Brigadier Gen. William Barton, and also, of Captain Stephen Olney. Northeastern University Women Writers Project, publication pending. https://www.wwp.northeastern.edu/texts/williams.revolutionary.html. [Original source: Williams, Catherine Read (Arnold). Biography of revolutionary heroes; containing the life of Brigadier Gen. William Barton, and also, of Captain Stephen Olney, Providence, RI, 1839. University of Michigan Library E207.B25 W7.]
[1] We have been focusing on intra- rather than inter-document complexity, but all of the issues around complexity we discuss here will be magnified as the set of documents in a system become more heterogeneous.
[2] See, for example, Basci & Misra (2009) and Stührenberg & Wurm (2010).
[3] The relevance of which is reinforced by the fact that 67% of the peer reviews of our paper recommended that we reference it.
[4] Although to be fair, and to provide some
foreshadowing, this XML does not seem to be nearly as
imposing (at least to us) after some formatting that
introduces ignorable whitespace; see Figure 3.
Figure 3 A 1,360-character subset of the XML from
Figure 2, which contains a single
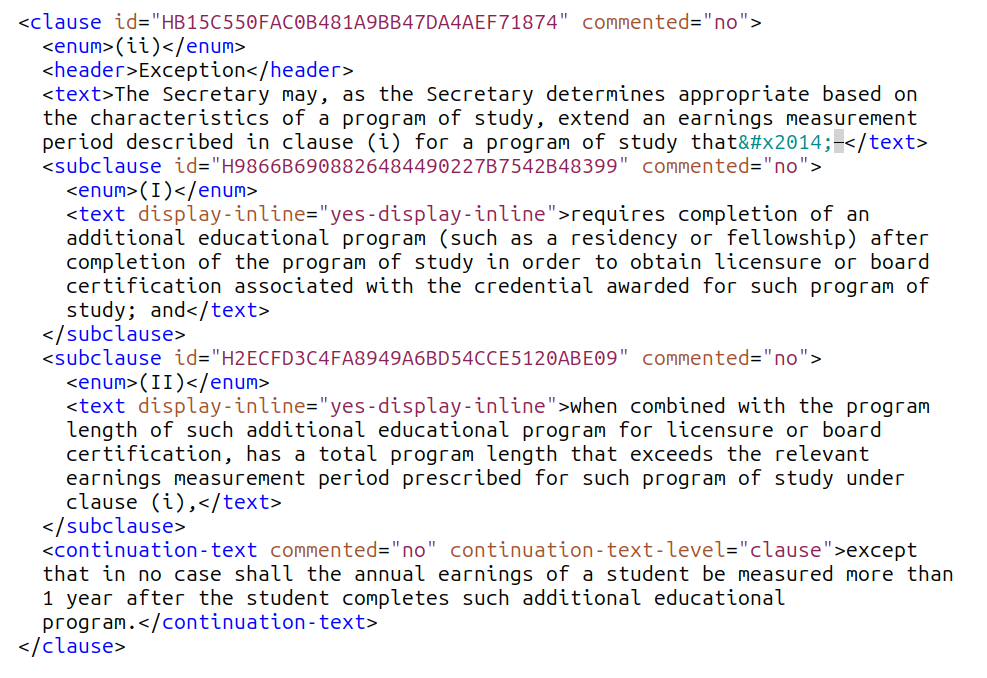
<clause> element, and has been
formatted for human readability by the insertion
of ~100 space and newline characters.
[5] <hyperDiv> functions similarly to the
TEI’s <standOff>
element, which was added many years after the WWP developed
<hyperDiv>.
[6] Currently only seven element types are permitted as
children of <hyperDiv>.
[7] Adding @source and linking to a bibliography
does add some syntactic complexity. Nevertheless, while this
encoding is useful for analyzing Emerson’s sources, it is not
necessary to produce the semantic complexity inherent in
delimiting and describing her intertextual gestures with
<itg> or <quote> and
@type.
[8] For a full list of values and definitions, see https://www.wwp.northeastern.edu/lab/emerson-networks/about.html.
[9] Which, generally speaking, is pretty easy to do, but in some rare cases, is very difficult, e.g., the aforementioned soft hyphens.
[10] As has been widely discussed, application complexity also
occurs when the precise edges of XML encoding are applied to
phenomena that have much less precise boundaries. In the TEI,
for instance, the @ana attribute can be used to
apply a project’s interpretive annotations to and within
texts. It can be extraordinarily useful to tag things like
language related to imperialism
or figurative language.
However, it can also be extraordinarily difficult to determine
whether @ana should be applied to individual words,
phrases, paragraphs, or entire divisions. Imagine, for instance,
tagging irony within A Modest Proposal or the theme of Man
vs. Nature
in On Walden Pond.
[11] Because the WWP’s documentation is encoded in XML, this
question can be investigated through the markup. The WWP uses an
<eg> element to tag examples in its internal
documentation. From a set that contains 139 documentation
entries (as of summer 2026), the mean number of
<eg> elements per entry is 2.44, and the median is 2. The
entries with the largest numbers of examples are:
<name> (16), <orgName> (11),
<placeName> (10), <persName>
(10), and <date> (9), suggesting that these have
particularly high degrees of application complexity relative to
the other elements the WWP uses.
[12] Syntax highlighting is also relevant here — for some humans, it dramatically improves readability, while others may find it a distraction.
[13] Of course, if you are primarily interested in how long it will take to parse a document, syntactic complexity is the thing that matters.
[14] The WWP uses 23 different keywords as of summer 2026.
[15] Because the number of potential valid values for @rend in this system is very, very high, the WWP does not validate rendition ladders during data entry, but instead in a set of post-encoding checks using Schematron and XQuery.
[16] Few things are more terrifying to a project manager than discovering that an encoder apparently forgot they had declared a renditional default halfway through encoding a document.
[17] We are not, for a moment, suggesting this is a bad thing; in many if not most projects this is an appropriate shift.
[18] Unlike complexity scores, questions on familiarity were optional, but only one respondent skipped these questions.
[19] Although, interestingly, one metric
ranked the five sample files in the exact reverse of the order of
average rankings by the humans: the average number of content nodes
per element type. A content node
is defined as a text
node that has at least one non-whitespace character. For every
element type, the total number of child (not descendant) content
nodes of all instances of that type is counted. The mean of those
totals is reported for this candidate metric. We have, as of yet,
made no effort to ascertain why this might be an inverse predictor
of complexity.