Introduction
When I have an idea for a paper, I like to check if someone has already presented it or something similar. If it's not a new topic, then maybe I can build on what's gone before — but I need to know what that was. There are also occasions when the research is not driven by a prospective project but simply curiosity or to support learning.
Fortunately, in the domain of XML and, more broadly, markup, a wealth of past papers are published online, by the organisers of conferences such as this and sister events. The search and indexing options provided by each event vary. Balisage is exceptional for maintaining a Master Bibliography, listing all the papers from all its meetings, plus author and topic indexes for the same complete corpus. For most other events, search is scoped per meeting so a literature search involves repeating the same query many times, not just per conference website but (in most cases) per each issue of the proceedings.
General purpose search engines, such as Google, are useful when the scope is broad.
Relevant matches from Balisage are often included in the first page of results, but
sadly this is less common for results from other events, leading to low confidence
in the comprehensiveness of such searches. A potential workaround on Google is to
use site: to limit the scope of the search to a specific website, but this still requires repeating
the query per site.
Each time I go through this process, I think to myself, Wouldn't it be nice if there was a centralised index of all the markup papers?
This paper is a case study on the creation of (somewhat) such an index, in particular
its scope, processes, challenges and solutions.
What is the Sisterhood?
On the home page of Balisage, there is a section titled Sister Conferences & Related Events
. (See Figure 1.)
Figure 1: Balisage's list of sister conferences
A partial screenshot of the Balisage home page, showing the section listing sister conferences and related events.
The websites for the events listed in Figure 1 each feature a similar list. Table I collects together those lists and their headings.
Table I
How some markup events self-describe their relationship to each other.
| Event | List Heading | Events in list |
|---|---|---|
| XML Prague | Sister events | Markup UK; Balisage; XML Summer School; Declarative Amsterdam; Markup Forum; DocEng |
| Markup UK | Sister events | XML Prague; Balisage; Declarative Amsterdam; XML Summer School |
| Balisage | Sister Conferences & Related Events | Declarative Amsterdam; XML Prague; Markup UK; XML Summer School |
| Declarative Amsterdam | Sister conferences | Balisage; Markup UK; XML Prague; XML Summer School |
| XML Summer School | Sister Conferences | Markup UK; XML Prague; Declarative Amsterdam; Balisage |
| Markup Forum | Partner Events | XML Prague; xugs |
| xugs | no list | no list |
| DocEng | Sister event | XML Prague |
The data was collected by:
-
Making a list of all the
Sister events
listed by XML Prague. -
Visiting the website for each of the listed events and repeating step 1 for that event.
-
Repeating steps 1 and 2 until there were no new sister events to add to the list.
Figure 2 is a graphical representation of the network implied by that data.
Figure 2: A network graph of related markup events
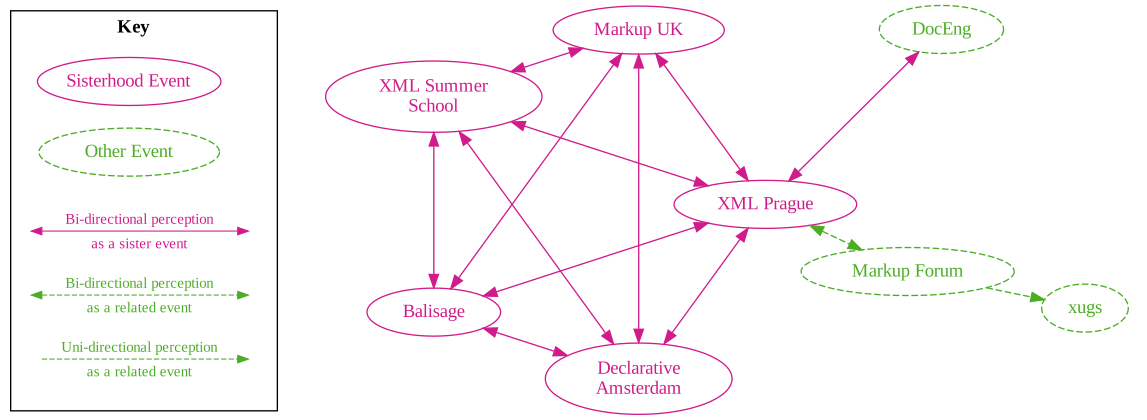
Showing how the events describe their relationships to each other.
Five events all bi-directionally self-describe as being related to each other (clockwise):
They are all either primarily about markup technologies or heavily feature them, and
the label these events use for their relationship is sister event
or sister conference
, so it seems obvious to collectively describe them as a sisterhood of markup events
.
Three events (DocEng, Markup Forum and xugs) are in the network but excluded from the sisterhood because they don't share a bi-directional relationship with all the events in the sisterhood.
In the past, other events would have appeared in this graph and potentially also the sisterhood, but they are no longer listed because they've ceased meeting, for example: XML London, XML Amsterdam. Collecting the data to extend the graph back in time is a more challenging task and was therefore deemed out-of-scope for the initial iteration of this project. The same currently applies for conferences that feature papers about markup or markup-related technologies but aren't linked to from any of the events in the network above. The purpose of this exercise was to identify a reasonable starting point for scoping data sources for the project.
Scoping the first iteration
According to Wikipedia, an index is:
A list of words or phrases (
headings) and associated pointers (locators) to where useful material relating to that heading can be found in a document or collection of documents.
For the initial iteration of the project, scope was limited to a title index, which is a type of heading index; more simply put, it's a list of titles in alphabetical order. Each entry consists of:
-
the title of a paper presented at an in-scope event
-
a list of the authors of that paper
-
the name and year of the event at which the paper was presented
-
a short excerpt of the abstract
Although XML Summer School is a member of the sisterhood, it is not an event that publishes papers, so it is currently deemed out-of-scope for this project.
Due to time constraints, content from Declarative Amsterdam is also absent from the first version of the index and also content from XML Prague prior to 2016.
Copyright
Indexing can be a contentious topic when it comes to copyright. It's impossible to create an index without accessing the content to be indexed, but under copyright law in many countries, it is illegal to make a copy of a substantial part of that content without permission of the copyright owner. It is commonly considered fair use to reproduce basic bibliographic metadata (title, author, publisher, publication date, etc.) but not abstracts [SoAcademia, Swansea, I4OpenAbstracts, Kinstellar].
While the output of this project respects these obligations, this project relies on the goodwill of the organisers of the events indexed, as the methodology followed might be interpreted as meeting only the spirit of the law, rather than its letter. An objective of the project is to increase the visibility and use of these papers by making them easier to find, and consequently also to raise awareness of the events that publish them; redirecting web traffic back to the event sites is a high priority.
Methodology
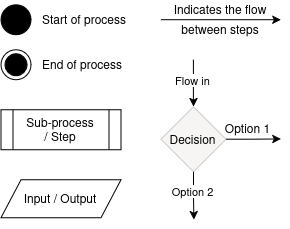
Figure 3 provides a very high-level overview of the end-to-end process, from collating the source data to storing the generated HTML index page. For a key to the symbols in this and subsequent process diagrams, see Appendix 1.
Using XProc 3.1, the data flows from one step to another, held in memory unless explicitly stored. This means that it's not necessary to store the retrieved source content, nor even the standardised, aggregated intermediary; only the generated HTML index page.
Figure 3: High-level process overview
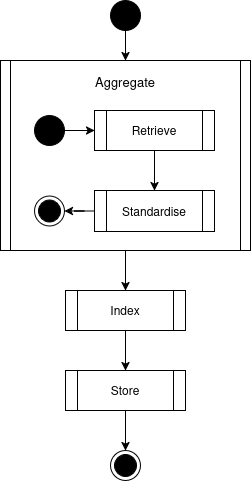
The main stages in the end-to-end process.
However, during development, options were implemented to enable storing the intermediary inputs and outputs, to support:
-
debugging, and
-
to avoid spamming the event websites with a multitude of requests each time a tweak was made, for example, to improve whitespace handling.
Storage option 1 was implemented using <p:store use-when="$debug = true()" … />. A common pattern to support debugging during XProc development, controlled by a
boolean parameter ($debug). In this project, the default value of $debug is false(), but that can be overridden at runtime. When set to true(), whatever input is fed into the p:store step is saved within a debug directory; a temporary storage location that is deleted manually, ad-hoc.
Storage option 2 is controlled per event, via attributes in the sources XML file that
is fed into the pipeline as its initial input (see Appendix 2). When /s:sources/s:event/@store is set to true(), the application saves a copy of any retrieved sources on the local filesystem.
If /s:sources/s:event/@retrieve is set to false(), then the application attempts to load sources from the local filesystem. The default
mode is to retrieve without storing. However, it isn't possible not to retrieve unless a snapshot of content has previously been saved and is still available. While
convenient, the process doesn't depend on storing retrieved content locally, and this
is also deleted manually ad-hoc.
Another convenience implemented during development is a control to target specific
events or sources. If s:event/@include is set to false(), then the sources from that event aren't retrieved or processed. Similarly, if s:source/@include is set to false(), then that specific source isn't retrieved or processed, even if the include flag
for the event it's associated with is set to true(). This latter use case is illustrated in the settings for XML Prague in Appendix 2 because the application hasn't yet been updated to handle sources earlier than 2016.
Sub-processes
The diagrams below aim to provide a summarised view of the main sub-processes involved in creating the title index.
Aggregation
The input into the Aggregate sub-process (Figure 4) is expected to be a file that conforms to the sources content model (namespace:
http://xylarium.org/ns/xml/grammars/salix/sources, schema: https://github.com/Xylarium/salix/blob/main/schemas/sources.rnc). See Appendix 2 for an example of a sources input file.
Figure 4: Sub-process: Aggregate
The sub-process that orchestrates collating source data from all events.
Collation
In this context, collate is being used to mean collect and combine data, and collation is the act of doing that.
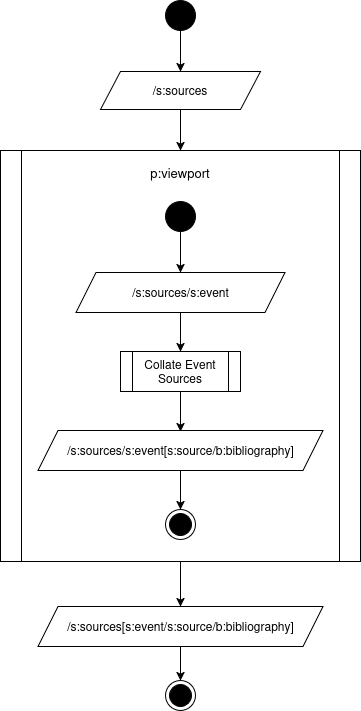
The sources for each event are collated separately (Figure 5), using the core XProc 3.1 step p:viewport to iterate through each /s:sources/s:event. This step leaves the /s:sources wrapper unchanged, modifying only the s:event and its contents.
By the end of this step, it's expected that each source will contain a bibliography
of all the sessions documented in the source, conforming to a custom content model
(namespace: http://xylarium.org/ns/xml/grammars/salix/bibliography, schema: https://github.com/Xylarium/salix/blob/main/schemas/bibliography.rnc).
For Markup UK each source usually documents all the sessions for a multi-day occurence of the conference. For XML Prague, sources for events after 2015 document all sessions in a single day of the conference: one source per day. Before 2016, like Markup UK, the sources for XML Prague document all the sessions across all the days of the conference: one source per year. For Balisage and Declarative Amsterdam, a single source documents all the sessions held during all occurrences of the conference: just one source document.
Some sources already include the abstract, but, if not, once the source has been standardised
and converted to a bibliography, p:viewport is again used to loop over each of the entries (b:bibliography/b:entries/b:entry) and attempt to retrieve an abstract for it. If found, that too needs to be standardised
before insertion into the b:entry.
Figure 5: Sub-process: Collate Event Sources
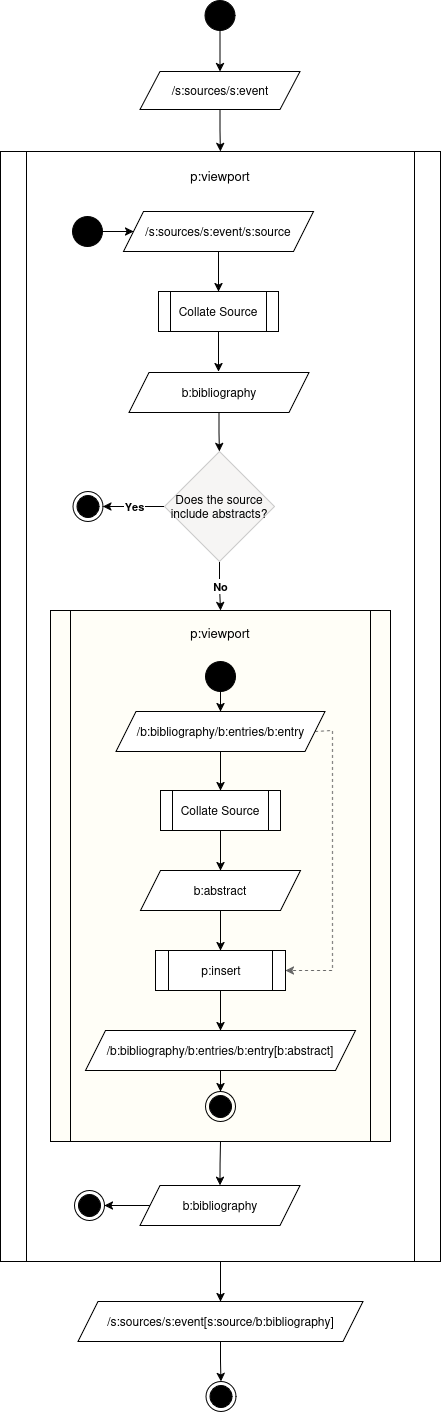
The sub-process that orchestrates retrieving and standardising source data per event.
Figure 6 shows the same basic sub-process that is used for retrieving and standardising the
data for an individual source, regardless of whether it is a literal s:source or, if attempting to retrieve an abstract, an b:entry.
Figure 6: Sub-process: Collate Source
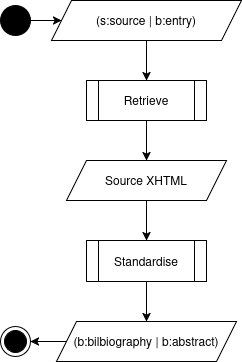
The sub-process that orchestrates retrieving and standardising each individual source or abstract.
Retrieval
The standard XProc 3.1 step for making an http-request (p:http-request) is used to retrieve source data from its remote host (see Figure 7).
As the response is sometimes HTML5, p:cast-content-type is used to convert it to well-formed XHTML; another standard XProc 3.1 step.
Figure 7: Sub-process: Retrieve Source
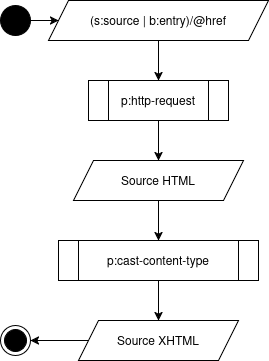
The sub-process that orchestrates retrieving an individual source or abstract from an event's website.
An error will be thrown if the input doesn't include a URL to submit the request to, exiting the application. However, if the response to a request is an error, it's caught and logged but shouldn't end the process; the result of this sub-process would be a copy of the input fed into the step.
Standardisation
The most challenging aspect of this project has been transforming the retrieved content into a standardised intermediary structure.
Although all the sources are some version of HTML, each event has used different structures and semantics to markup their content. Unsurprisingly, because content models evolve over time, these factors also often vary between sources from the same event.
There is also variation in the scope and purpose of the source documents. The organisers of Balisage maintain an excellent Master Bibliography that includes all the published sessions from Balisage meetings since 2008. The organisers of Markup UK and XML Prague don't maintain a master bibliography, and the sources this project chose to use from these events are primarily intended to serve as schedules, not conduits of bibliographic data.
Figure 8: Sub-process: Standardise Source
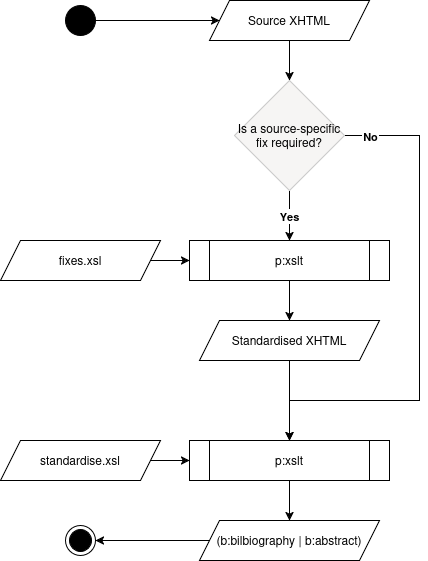
The sub-process that orchestrates standardising an individual source or abstract.
There are several advantages to standardising the content prior to indexing:
-
It supports simplicity in the indexing process because the inputs conform to a single content model, so the only logic required is for generating the index.
-
During development, validating against an expected content model can help to flag up missing or unexpected data and highlight previously unnoticed differences between sources.
-
Automated validation can be used to detect flaws in the content at the earliest possible point in the process, which can be used to halt the process if the nature of the flaw means it would be a waste of time to continue past that point.
-
The standardisation logic varies between events but some of it may be relevant to multiple sources within an event. Figure 8 simplifies the actual process somewhat, as it is sometimes the case that multiple fixes need to be applied, and rather than bundling them in a single stylesheet (
fixes.xsl), the fix for each known problem has its own stylesheet, and they're applied incrementally. This helps when a fix isn't working as it's possible to compare the results from each step to pin-point exactly where the problem occurs.
If the content isn't standardised beforehand, then logic to handle the differences in source structure and semantics would need to be interwoven with the logic to create the index. This would make the index stylesheet more complex and thus more difficult to read, understand and maintain. As more indexes are created, it's likely that the standardisation logic would need to be duplicated in each index stylesheet. Making the indexing stylesheets modular, so that the standardisation logic could be shared across them, might help, but the two concerns would still largely need to be separated to avoid duplication.
There are surprisingly few classes of fix
that need to be made. Most commonly they involve:
-
Enriching the source markup with missing or more detailed semantic markup, for example, by adding class names or additional structural wrappers.
-
Deleting empty elements.
-
Tidying up lists of contributors:
-
Ensuring the expected delimiters are present.
-
Clearly separating a contributor's affiliation from their name.
-
-
Correcting structural anomalies; usually a paragraph in the wrong place.
An unexpected workaround unique to Markup UK 2021 was the need to un-comment the conference schedule; the page included a third-party javascript widget which may have originally used the comments as a data source. Happily,, this approach was only used for one year, when the conference met virtually as a consequence of the COVID-19 pandemic.
Indexing
Once the source content has been aggregated and standardised, it is easy to create a title index using a single, simple XSLT stylesheet.
Figure 9: Sub-process: Index
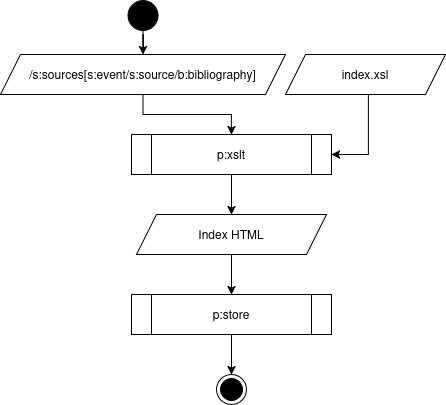
The sub-process that generates an index from the result of the aggregation process.
Version 1.0.0 of the title index contains 894 entries, from 3 events (Balisage, Markup UK, XML Prague). See Figure 10 for a screenshot of the first 6 entries.
Figure 10: Title index
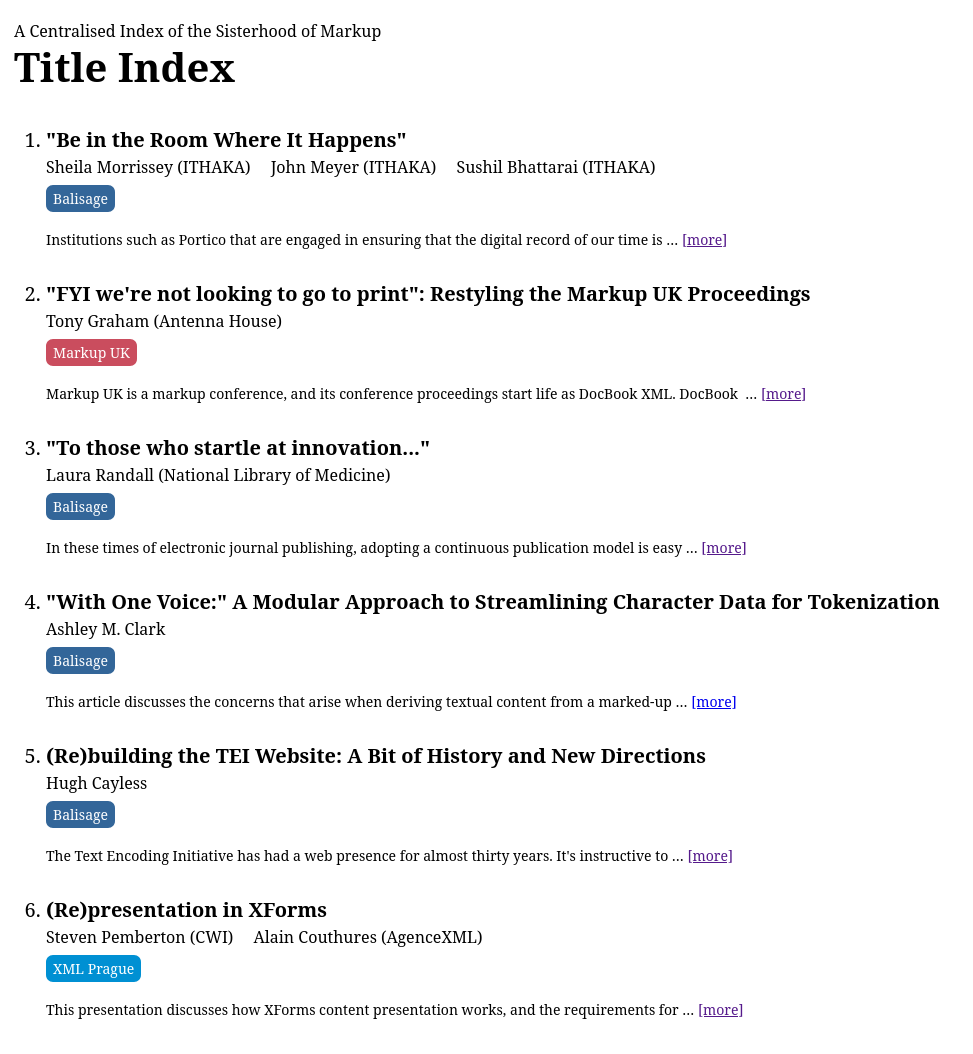
A screenshot of the first few entries in the first version of the title index.
The entries are sorted alphabetically. A potential future improvement is to ignore punctuation during sorting.
The title of each entry links back to the event website from which its data was sourced;
ideally to the paper itself. The same URL is used for the [more] link at the end of the abstract excerpt. The event name lozenge links to the current
home page of the event.
The most complicated aspect of this transformation (which still isn't very complicated) is creating the abstract excerpt:
-
Use
fn:substringto get the first 100 characters of the string value of the abstract. -
If the result of step 1 doesn't end with a space (
fn:ends-with), it may end with a partial word, so usefn:tokenizeto drop everything after the last space and thenfn:string-jointo stitch the tokens/words back together again. -
If the result of step 2 ends with a colon, drop the colon.
-
Append an ellipsis to indicate that this is an excerpt.
-
Append a
[more]link, inviting the reader to go to the original source if they wish to read on.
The majority of the above steps exist only to implement optional stylistic preferences.
This project began as an attempt to aggregate information about papers presented at the sisterhood of markup conferences, but, at time of writing, the entries represent a variety of different types of sessions, not all of which are associated with a paper. Known types of session are:
-
presenting a paper
-
workshop
-
user-group meeting
-
an opening or closing talk
Further analysis is required to check for other types of sessions and develop a methodology for reliably identifying each type. It's likely that that would then support an option for index users to filter by session type, rather than exclude non-paper sessions during the collation process.
Going live
The title index was published just before this paper was presented, on Friday 7th of August, 2026, at https://xylarium.github.io/salix/sessions/.
Event indexes
Happily, there was also time, post-submission, to extend the publishing process to generate a collection of event indexes:
-
the top-level event index, that lists all the events represented in the title index and the range of meeting years indexed (see Figure 11);
-
a profile page for each of the events, that includes: a link to the homepage of the event's website, a chronological list of all its indexed meetings, and the total number of indexed sessions per meeting (see Figure 12);
-
a profile page for each of the event meetings, that lists all the indexed sessions from that meeting, effectively providing a meeting-specific title index (see Figure 13).
Figure 11: Events list
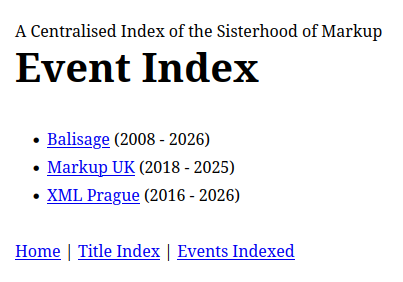
A screenshot of the top-level event index.
Figure 12: Event profile
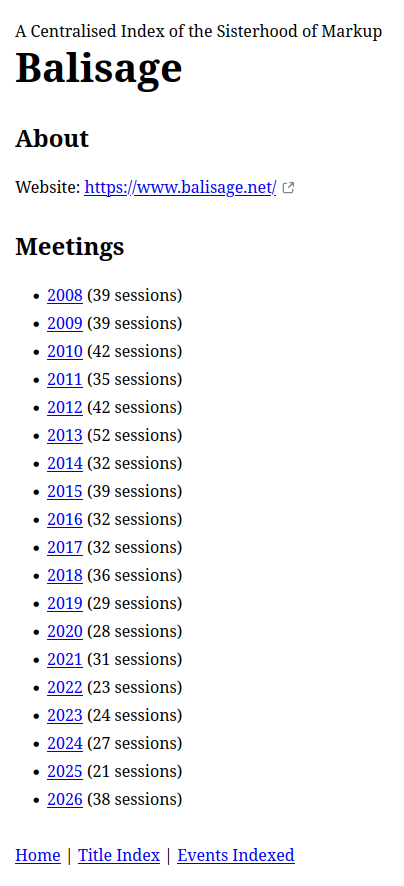
A screenshot of the event profile for Balisage.
Figure 13: Meeting profile
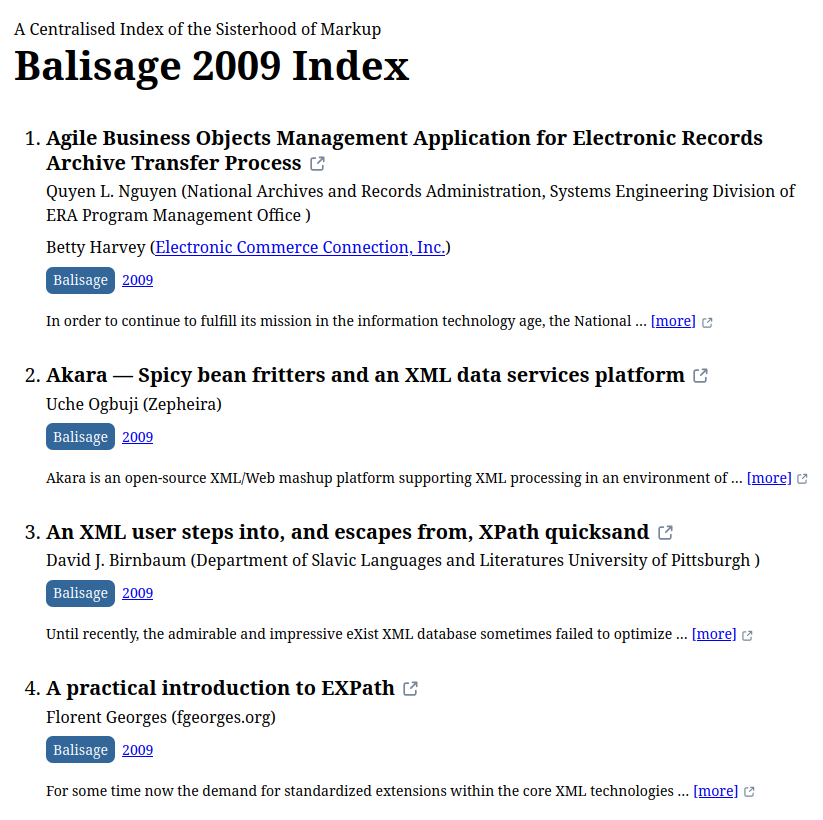
A partial screenshot of the meeting profile for Balisage, 2009, showing the first 4 entries in the index.
The meeting indexes are generated from the same aggregated, standardised data that
the title index is generated from. Consequently, it was possible to re-use some of
the XSLT written for the title index. This was implemented by moving the common logic
and settings into shared.xsl. Continuing the theme of separating concerns, there is a dedicated stylesheet for
each of the classes of page that needs to be created (title index, events list, event profile, meeting profile) and each of these imports shared.xsl.
Essentials
The content and style of the website is minimalist, but there are a few basics that needed to be added to all pages in addition to their core content and a title:
-
style instructions - viewport settings and a CSS stylesheet (see Figure 15);
-
page header - the website title (see Figure 14 and Figure 15), which also provides a link back to the home page;
-
page footer - a site navigation menu (see Figure 14 and Figure 15) that provides links to each of the top-level pages.
shared.xsl includes a named template for each of these components, so that the markup and content
are consistent across all pages on the website and changes only need to be made once.
Figure 14: Visible global page components

An annotated screenshot of the home page, labelling the visible global page components.
Figure 15: XHTML markup

An annotated screenshot of the XHTML markup for the home page, labelling the global page components.
Updates
Now that the index is public, it will be important to keep it up-to-date. Technically, it should be possible to monitor the sources for changes, based on HTTP headers, and trigger an update if a change is detected. However, the monitoring service would need to be hosted somewhere, and extra error handling would need to be implemented to mitigate against automatically publishing a broken index. It would also be necessary to implement a process to predict and verify new source URLs and add those to the sources input file. With the closing of Balisage, in the future, sadly, there will probably be no more than a couple of events per year from which to incorporate new data. The low frequency of required updates means that the complexity and risk associated with automating updates are currently outweighed by the simplicity and lower risk of generating and applying updates manually.
Another question related to updates is how soon after the end of an event should the index be updated? And what happens if an event publishes a correction? The answer to both of these questions may yet still lie in automated change detection to raise an alert.
Potential future work
-
Index papers from:
-
XML Prague, prior to 2016
-
Declarative Amsterdam
-
events that have ceased meeting, such as XML London, XML Amsterdam
-
related events, such as JATS-Con
-
-
Create more heading indexes:
-
author index
-
subject index
-
-
Create author profile pages, containing:
-
statistics (total papers published, total events)
-
a chronological list of their papers
-
-
Display the version number on each index, plus when the source content was last updated.
-
Implement automated validation checks.
-
Publish the indexes as XML as well as HTML.
-
Differentiate between types of session, e.g., paper, workshop, user group meeting, introduction, closing summary, and supporting filtering by type.
-
Ignore punctuation when sorting titles.
-
Replace the custom Salix content model for a bibliography with one from a more commonly used standard, such as JATS, BITS or DocBook.
-
An option to generate bibliomixed citation markup for selected entries.
Conclusion
While it would be nice if there was a centralised index of all the markup papers, that dream is too broad for the first iteration of the project; even the reduced scope (all sessions from the sisterhood of markup events that publish papers) turned out to be unachievable in the time available. However, the site has already been of use to me, to check (after the fact) that no one seems to have written about attempting this endeavour before (within the corpus of sessions indexed so far, at least). As a side-effect, I also now have a growing list of recently discovered interesting papers to read. I hope that this resource will prove similarly useful to others too.
As this project progressed, two central themes emerged: separation of concerns, and consistency. XSLT and XProc were obvious technology choices for implementing an application that needed to consume, transform and generate XHTML as it is essentially XML, and this is the format that they were originally primarily designed to process. Anyone who is familiar with the latest versions of these languages will know that they are also extremely well suited for implementing a flexible, incremental process and supporting re-use. The former is exactly what you need when you are trying to isolate discrete steps and apply them conditionally, and the latter is essential for consistency. Together, these technologies made implementing the process so easy that the challenges all lay in dealing with the (expected and unexpected) lack of consistency in the source data.
In addition to updating the indexes to include sessions presented at future meetings, work is also on-going to add in the missing historical content from XML Prague (prior to 2016) and Declarative Amsterdam. Once those are complete, the next step will be selected from the potential future improvements already identified (above) or suggested by users. If there's a feature that you would like implemented, please suggest it by raising an issue at https://github.com/Xylarium/salix/issues.
Appendix 1. A Key to the Symbols used in the Process Diagrams
Appendix 2. Source Data Manifest
The aggregation process depends knowing which sources to retrieve and collate. These
are listed in a manifest file that is required to conform to a custom, project-specific
content model, known internally as the sources
content model.
Figure 16: Sources content model

A diagram enumerating the entities in the content model (rectangles) and their properties (ovals).
If you are used to the way that Balisage models events, in particular, then Figure 17 may be helpful as it shows how that differs from the model used by this project.
Figure 17: Alternative approaches to modelling events

A side-by-side comparison of the conceptual event models used by this project and Balisage.
Below is a partial sample of a sources data manifest.
<?xml version="1.0" encoding="UTF-8"?>
<?xml-model href="http://xylarium.org/ns/xml/grammars/salix/sources" type="application/relax-ng-compact-syntax"?>
<sources xmlns="http://xylarium.org/ns/xml/grammars/salix/sources" xmlns:m="http://xylarium.org/ns/xml/documentation">
	<event id="balisage" include="true" retrieve="true" store="false" standardise="true" href="https://www.balisage.net/" name="Balisage">
		<source href="https://www.balisage.net/Proceedings/bibliography.html" />
	</event>
	<event id="xml-prague" include="true" retrieve="true" store="false" standardise="true" href="https://www.xmlprague.cz/" name="XML Prague">
		<source href="https://archive.xmlprague.cz/2005/program.html" include="false" />
		<source href="https://archive.xmlprague.cz/2006/program.html" include="false" />
		<source href="https://archive.xmlprague.cz/2007/program.html" include="false" />
		<m:note>
			<m:p>No event in 2008</m:p>
		</m:note>
		<source href="https://archive.xmlprague.cz/2009/sessions.html" include="false" />
		<source href="https://archive.xmlprague.cz/2010/sessions.html" include="false" />
		<source href="https://archive.xmlprague.cz/2011/sessions.html" include="false" />
		<source href="https://archive.xmlprague.cz/2012/sessions.html" include="false" />
		<source href="https://www.xmlprague.cz/sessions2013/" include="false" />
		<source href="https://www.xmlprague.cz/sessions2014/" include="false" />
		<source href="https://www.xmlprague.cz/sessions2015/" include="false" />
		<source href="https://www.xmlprague.cz/day1-2016/" />
		<source href="https://www.xmlprague.cz/day2-2016/" />
		<source href="https://www.xmlprague.cz/day3-2016/" />
		<source href="https://www.xmlprague.cz/day1-2017/" />
		<source href="https://www.xmlprague.cz/day2-2017/" />
		<source href="https://www.xmlprague.cz/day3-2017/" />
		<source href="https://www.xmlprague.cz/day1-2018/" />
		<source href="https://www.xmlprague.cz/day2-2018/" />
		<source href="https://www.xmlprague.cz/day3-2018/" />
		<source href="https://www.xmlprague.cz/day1-2019/" />
		<source href="https://www.xmlprague.cz/day2-2019/" />
		<source href="https://www.xmlprague.cz/day3-2019/" />
		<source href="https://www.xmlprague.cz/day1-2020/" />
		<source href="https://www.xmlprague.cz/day2-2020/" />
		<source href="https://www.xmlprague.cz/day3-2020/" />
		<source href="https://www.xmlprague.cz/day1-2022/" />
		<source href="https://www.xmlprague.cz/day2-2022/" />
		<source href="https://www.xmlprague.cz/day3-2022/" />
		<source href="https://www.xmlprague.cz/day1-2024/" />
		<source href="https://www.xmlprague.cz/day2-2024/" />
		<source href="https://www.xmlprague.cz/day3-2024/" />
	</event>
</sources>
References
[Balisage] Balisage: The Markup Conference
. https://www.balisage.net/ (accessed April 11, 2026).
[XMLPrague] XML Prague
. https://www.xmlprague.cz/ (accessed April 11, 2026).
[DocEng] DocEng: The ACM Symposium on Document Engineering
. https://doceng.org/ (accessed April 11, 2026).
[MarkupF] <Markup Forum/>
. https://www.markupforum.de/ (accessed April 11, 2026).
[Xugs] ./xml_user_group_stuttgart
. https://xugs.de/ (accessed April 11, 2026).
[MarkupUK] Markup UK
. https://markupuk.org/ (accessed April 11, 2026).
[DecAmSis] Declarative Amsterdam. Sister conferences
. https://declarative.amsterdam/sister-conferences/ (accessed April 11, 2026).
[XMLSumS] XML Summer School
. https://xmlsummerschool.org/ (accessed April 11, 2026).
[XMLLon] XML London
. https://xmllondon.com/ (accessed April 11, 2026).
[XMLAm] XML Amsterdam
, Internet Archive. https://web.archive.org/web/20210225015112/http://www.xmlamsterdam.com/ (accessed April 11, 2026).
[WikipIndex] Wikipedia contributors. Index (publishing)
. In Wikipedia, The Free Encyclopedia. https://en.wikipedia.org/w/index.php?title=Index_(publishing)&oldid=1347240285 (accessed April 12, 2026).
[BalMBib] Balisage Series on Markup Technologies. Master Bibliography
. https://www.balisage.net/Proceedings/bibliography.html (accessed April 11, 2026).
[XProc31] XProc Next Community Group. XProc 3.1: An XML Pipeline Language
. https://spec.xproc.org/lastcall-2024-08/head/xproc/ (accessed April 11, 2026).
[XProc31SL] XProc Next Community Group. XProc 3.1: Standard Step Library
. https://spec.xproc.org/3.1/steps/ (accessed April 11, 2026).
[SoAcademia] Stack Overflow Academia contributors. Can I collect meta information on papers and put this online?
. https://academia.stackexchange.com/questions/26479/can-i-collect-meta-information-on-papers-and-put-this-online (accessed August 4, 2026).
[Swansea] Swansea University. Copyright: Information for Researchers
. https://libguides.swansea.ac.uk/copyright/researchers (accessed August 4, 2026).
[I4OpenAbstracts] Initiative for Open Abstracts. Frequently Asked Questions
. https://i4oa.org/faqs.html (accessed August 4, 2026).
[Kinstellar] Kinstellar. Liability of search engines for copyright infringement under Czech law
. https://www.kinstellar.com/news-and-insights/detail/13/liability-of-search-engines-for-copyright-infringement-under-czech-law (accessed August 4, 2026).